
Aligning What Matters: Object-Centric and Structure-Aware Feature Alignment for Heterogeneous Collaborative Perception
IEEE 103rd Vehicular Technology Conference (VTC2026-Spring), Nice, France, 2026年6月9日
3行要約
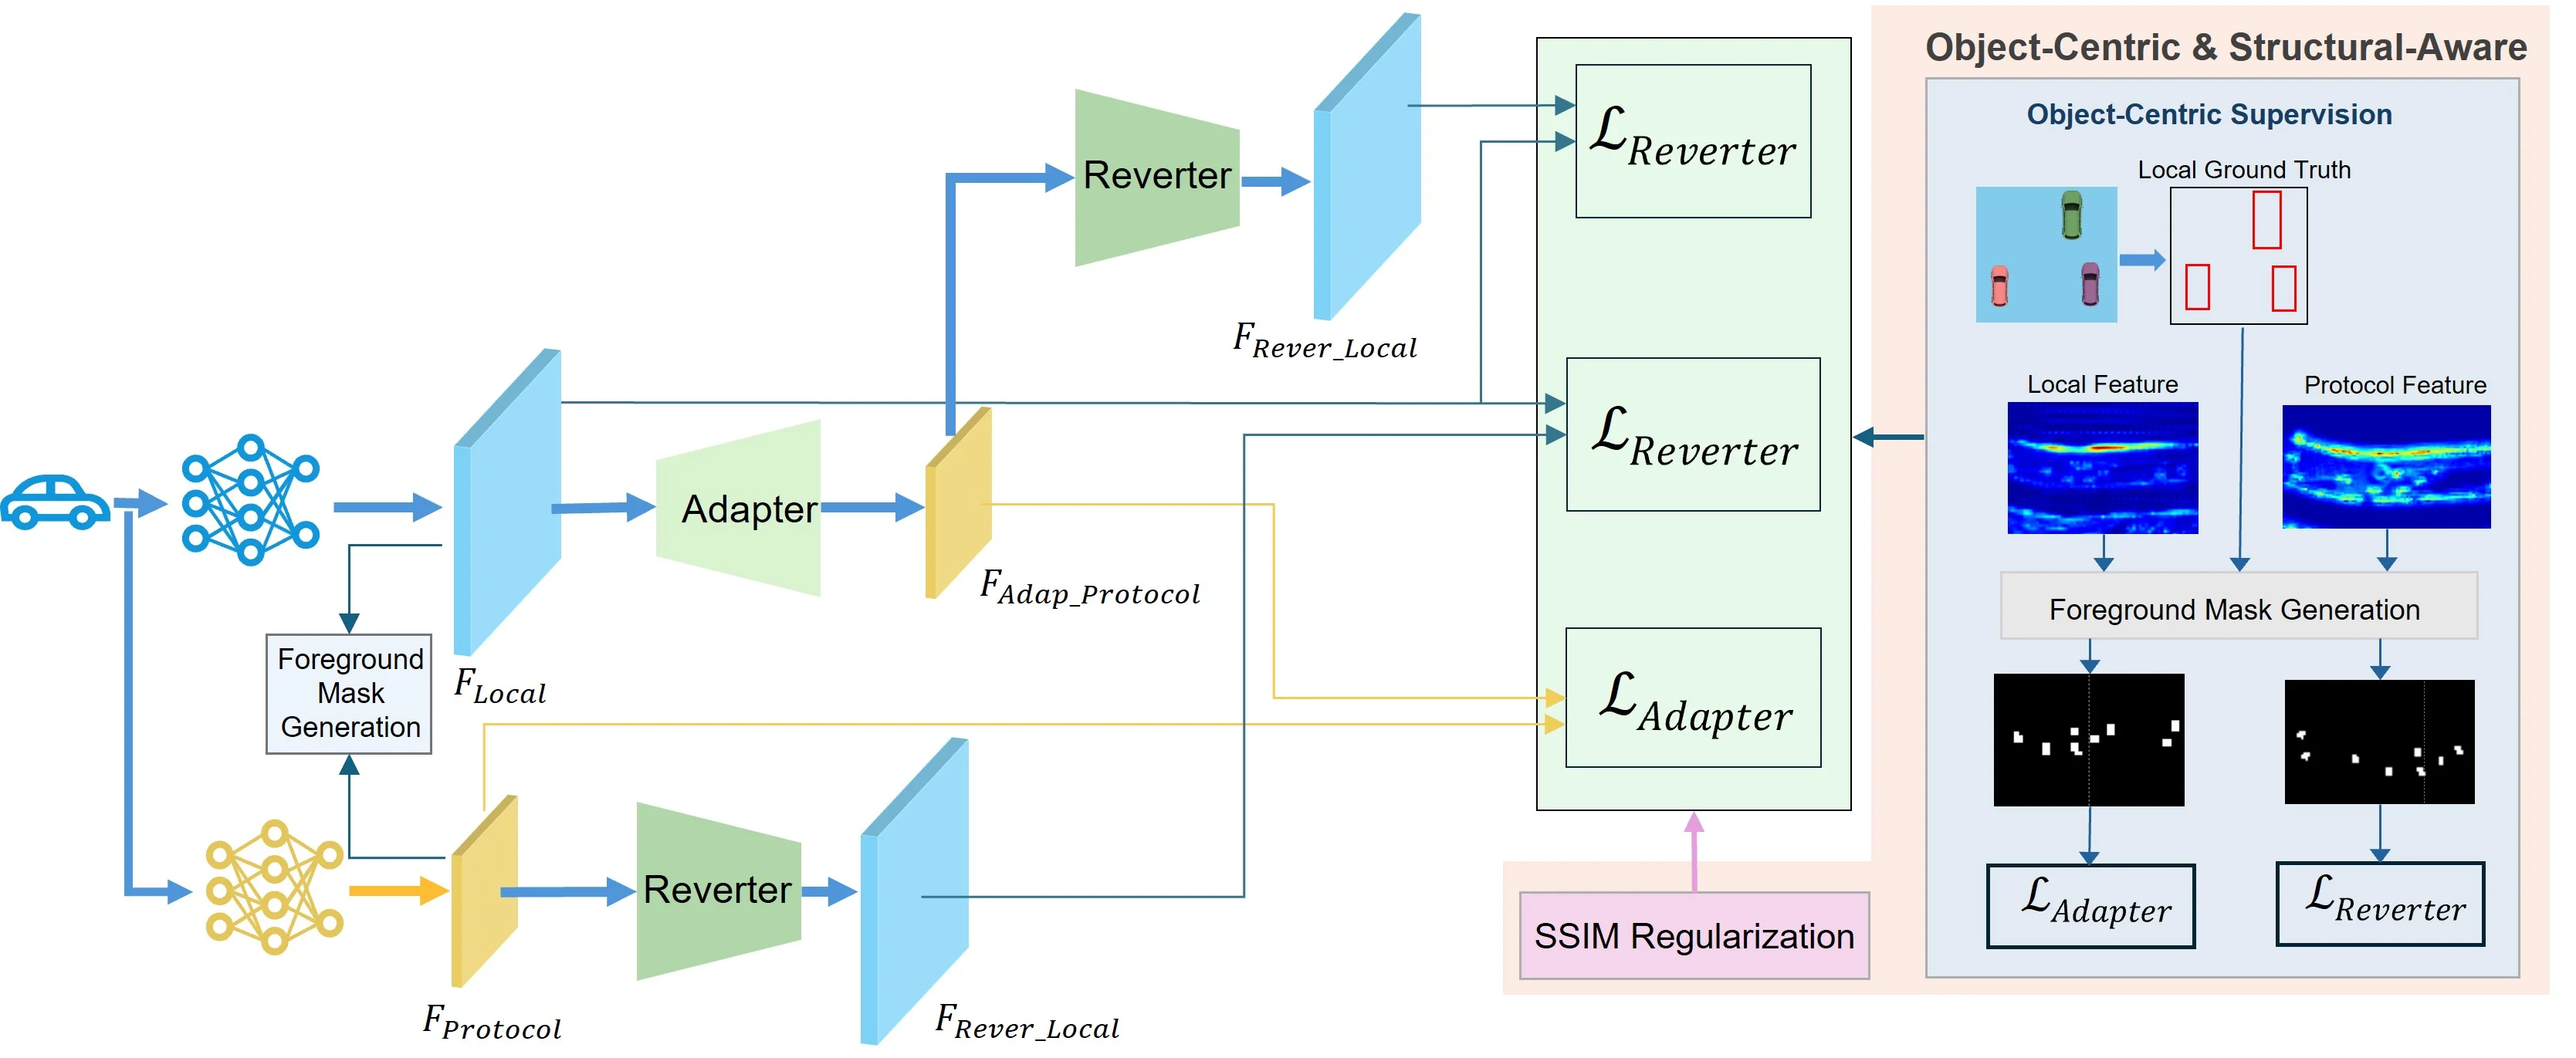
- 異なる認識モデル間で特徴をそろえる際、検出対象の物体を重視する。
- 軽量なアダプタと逆変換器を使い、前景の細部と局所構造を共有表現で保つ。
- 検出を重視した整合が協調3D物体認識を改善するか、実験で評価した。
論文の図
アブストラクト(原文)
Collaborative perception enhances autonomous driving by enabling vehicles to jointly reason about the environment. Feature-level sharing is particularly attractive, as it preserves rich spatial information and allows uncertain regions to be jointly refined before object inference. However, in realistic deployments, vehicles often rely on heterogeneous perception backbones and preprocessing pipelines, resulting in substantial domain gaps that make feature fusion unreliable. Recent protocol-domain adapter frameworks mitigate this issue by mapping heterogeneous features into a shared latent space, but their alignment objectives are typically defined over the entire Bird’s Eye View (BEV) grid. Since foreground objects occupy only a small fraction of BEV space, such global reconstruction objectives are dominated by background regions and provide weak supervision for aligning detection-critical features. Moreover, purely global alignment does not explicitly preserve fine-grained spatial structures that are essential for accurate 3D object detection. In this work, we revisit protocol-domain alignment from the perspective of detection relevance and structural consistency. We propose an object-centric and structure-aware adapter for heterogeneous collaborative perception. Specifically, we introduce BEV foreground masks derived from 3D bounding boxes to emphasize object regions during alignment, and incorporate a Structural Similarity Index Measure (SSIM)–based objective to enforce fine-grained structural consistency across heterogeneous feature domains. Importantly, the proposed method preserves the plug-and-play property of protocol-domain collaboration and requires no modification of the original perception backbones or fusion modules. Extensive experiments under diverse heterogeneous configurations demonstrate consistent improvements over protocol-domain adapter baselines, achieving up to +0.19 AP@0.7 under challenging modality settings.
引用方法
D. Li, E. Javanmardi, and M. Tsukada, “Aligning What Matters: Object-Centric and Structure-Aware Feature Alignment for Heterogeneous Collaborative Perception,” in IEEE 103rd Vehicular Technology Conference (VTC2026-Spring), Nice, France, 2026.
BibTeX
@inproceedings{Li2026b,
  title         = {Aligning What Matters: Object-Centric and Structure-Aware Feature Alignment for Heterogeneous Collaborative Perception},
  author        = {Donghui Li and Ehsan Javanmardi and Manabu Tsukada},
  year          = {2026},
  date          = {2026-06-09},
  booktitle     = {IEEE 103rd Vehicular Technology Conference (VTC2026-Spring)},
  address       = {Nice, France},
  abstract      = {Collaborative perception enhances autonomous driving by enabling vehicles to jointly reason about the environment. Feature-level sharing is particularly attractive, as it preserves rich spatial information and allows uncertain regions to be jointly refined before object inference. However, in realistic deployments, vehicles often rely on heterogeneous perception backbones and preprocessing pipelines, resulting in substantial domain gaps that make feature fusion unreliable. Recent protocol-domain adapter frameworks mitigate this issue by mapping heterogeneous features into a shared latent space, but their alignment objectives are typically defined over the entire Bird’s Eye View (BEV) grid. Since foreground objects occupy only a small fraction of BEV space, such global reconstruction objectives are dominated by background regions and provide weak supervision for aligning detection-critical features. Moreover, purely global alignment does not explicitly preserve fine-grained spatial structures that are essential for accurate 3D object detection. In this work, we revisit protocol-domain alignment from the perspective of detection relevance and structural consistency. We propose an object-centric and structure-aware adapter for heterogeneous collaborative perception. Specifically, we introduce BEV foreground masks derived from 3D bounding boxes to emphasize object regions during alignment, and incorporate a Structural Similarity Index Measure (SSIM)–based objective to enforce fine-grained structural consistency across heterogeneous feature domains. Importantly, the proposed method preserves the plug-and-play property of protocol-domain collaboration and requires no modification of the original perception backbones or fusion modules. Extensive experiments under diverse heterogeneous configurations demonstrate consistent improvements over protocol-domain adapter baselines, achieving up to +0.19 AP@0.7 under challenging modality settings.},
  keywords      = {CRONOS, ITS},
  pubstate      = {published},
  tppubtype     = {inproceedings}
}