塚田研究室は、東京大学大学院 情報理工学系研究科 創造情報学専攻の研究室です。コンピュータネットワークとサイバーフィジカルシステムを基盤とし、協調型自動運転、混合現実、次世代通信、没入型メディアなど幅広い研究に取り組んでいます。

塚田研究室は、東京大学大学院 情報理工学系研究科 創造情報学専攻の研究室です。コンピュータネットワークとサイバーフィジカルシステムを基盤とし、協調型自動運転、混合現実、次世代通信、没入型メディアなど幅広い研究に取り組んでいます。
🇫🇷 Paris leg of our European tour!
On Oct 2 we visited VEDECOM in Versailles to meet the French team of our Japan–Europe collaboration on cooperative mobility, then headed to CentraleSupélec on the Paris-Saclay campus for an afternoon of in-depth research discussions. 🚗📡
Oct 3 was a reunion with Thierry Ernst, a long-time collaborator since the INRIA days of our ITS research. Great conversations, great food, and new ideas for working together. 🤝🥐
Merci beaucoup to everyone who welcomed us!
10月 6
A day of research, discovery, and great conversations at THI in Ingolstadt! 🚗🔬🇩🇪
Prof. Manabu Tsukada shared our lab’s research on connected and automated driving and explored the CARISSMA facilities, Car2X lab, and vehicle simulator.
Many thanks to Andreas Festag and the THI team for the warm welcome and fascinating lab tours—and to Andreas for showing us around Ingolstadt! 🤝
📸 Photos courtesy of Andreas Festag
📍 Ingolstadt, Germany | September 30, 2026
10月 1
Research, shared curiosity, and new connections in St.Gallen! 🇨🇭🤝
Our JST CREST Internet of Realities project joined the University of St.Gallen’s Interactions Research Group for a workshop on computing and human realities—with a visit to the Abbey Library and dinner together the following day. 📚🍽️
10月 1
🇮🇹 Four days at IEEE ITSC 2026 in Naples!
The 29th edition filled the Stazione Marittima on the port with about 1,100 researchers, 16 parallel rooms and 831 presentations. Three papers from our lab are in the proceedings, and Prof. Tsukada gave a keynote at the DriveX workshop on agentic AI for cooperative autonomous driving, plus an invited talk at W19 on bridging ground vehicles and aerospace systems.
And then the gala dinner happened, under the Neapolitan stars on the coast at Bacoli 💃🕺
#ITSC2026 #IEEEITSC #TLab #UTokyo #UniversityOfTokyo 東京大学 塚田研 Naples V2X AutonomousDriving
9月 20
🇸🇪 ECCV 2026 in Malmö! Our lab presented HERO: Heterogeneous Evidential Robust Object-Level Collaborative Perception, a way for vehicles with different sensors and detectors to share what they see without sharing huge feature maps.
By attaching evidential statistics to each detected box, HERO matches state-of-the-art feature-level fusion while cutting communication bandwidth by over 1000x, and it stays robust even under pose error and latency. 🚗📡
Great talks, great people, and a beautiful city. Thanks to everyone who stopped by! 🎉
#ECCV2026 #ECCV #TLab #UTokyo #UniversityOfTokyo 東京大学 塚田研 CollaborativePerception AutonomousDriving ComputerVision Malmö
9月 14
Real signals. Real crosswalks. Real rain. 🌧️
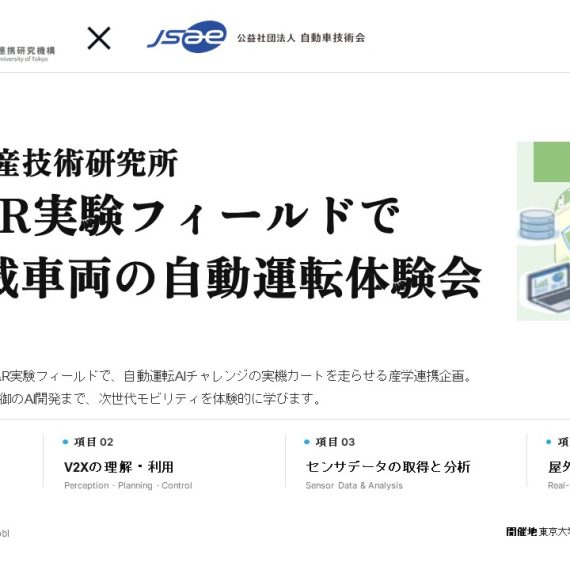
Three days of V2X hands-on at our ITS R&R experimental field in Kashiwa — the spin-off of the JSAE Automotive AI Challenge 2026, organized together with UTokyo UTmobI. The teams brought their karts, we brought the roadside units, and the weather brought the difficulty setting 🏎️⚡
Presentations and demo runs on day one, roadside debugging in between, and laptops still open long after sunset. That’s what a field experiment actually looks like 💜
#TLab #UTokyo #UniversityOfTokyo #東京大学 #塚田研 UTmobI JSAE AIChallenge2026 自動運転AIチャレンジ V2X AutonomousDriving ITS 柏キャンパス 自動運転
9月 12
That’s a wrap on CIV Summer School 2026 🌊🚗
Five days in Miyazaki with 38 participants from 19 institutions (11+ nationalities!) for the 6th edition of the Summer School on Cooperative Interacting Vehicles, held in Asia for the first time.
🎓 14 lectures
📌 16 posters
🤖 Hands-on with LiDAR and a real rover
💻 A data hackathon on fleet recordings from Kashiwa and Reims
🍢 And plenty of Miyazaki in between
Thank you to everyone who came, taught, asked, and stayed up late. See you at CIV 2027! 👋
Co-organized by The University of Tokyo, Mines Paris–PSL, Karlsruhe Institute of Technology, UC Berkeley and the German University in Cairo, with support from the IEEE Intelligent Transportation Systems Society.
#CIVSummerSchool #CIV2026 #CooperativeInteractingVehicles #AutonomousDriving #V2X SummerSchool Miyazaki Seagaia IEEEITSS TLab UTokyo UniversityOfTokyo 東京大学 塚田研
9月 4
Our joint summer retreat with Esaki Lab and Ochiai Lab in Nagano! 🏔️
Three labs, three days (July 31 – Aug 2), and nearly 30 of us came together for research presentations, deep discussions, and plenty of fun in between. 📚🤝
Great talks, great food, and great memories — already looking forward to the next one! 🎉
#TLab #UTokyo #UniversityOfTokyo #LabRetreat #Nagano
8月 2
Three guests, three countries, one lab. 🇰🇷🇫🇷🇯🇵
Prof. JaeSeung Song and Prof. Jong-Hyouk Lee (Sejong University) and Prof. Jean-Marie Bonnin (IMT Atlantique) joined us at UTokyo on July 28 to talk AI, security and future mobility networks — then dinner. Some collaborations start with a whiteboard, some with a good meal. 🍻
#UTokyo #東京大学 #塚田研究室 #SejongUniversity #IMTAtlantique 国際共同研究 AI 6G
7月 29
🇹🇭 TLab @ MIWA 2026 – Bangkok!
Our team joined MIWA 2026 — Mobility Interaction for a World in Action — at Chulalongkorn University in Bangkok.
Prof. Manabu Tsukada delivered a keynote talk, “Cooperative Intelligence for Autonomous Driving: From V2X to Human-Agent Interaction,” and moderated the session “AI Shaping the Future of Mobility Systems.”
Prof. Ehsan Javanmardi also attended the event together with our PhD students, Yun Li and Yu Asabe. Yun presented her work on trustworthy AI for autonomous driving, while Yu shared his research on cooperative maneuver coordination.
From inspiring discussions on AI, V2X, and future mobility to the technical tour at Thailand’s CAV Sandbox, it was a fantastic opportunity to exchange ideas with researchers and industry leaders from across Asia.
Thank you to the organizers and everyone we met in Bangkok!
7月 23
私たちの研究室では、自動運転、混合現実、次世代通信、デジタルツインなど、分野横断的なプロジェクトを推進しています。いずれのテーマも、理論研究から社会実装まで一貫して取り組み、実証実験や国際標準化活動を通じて社会に還元しています。現在は以下のようなプロジェクトに注力しています。
@article{Li2026g,
title = {Causal Scene Narration: Inference-Time Text Restructuring for Vision-Language-Action Driving},
author = {Yun Li and Yidu Zhang and Simon Thompson and Ehsan Javanmardi and Manabu Tsukada},
year = {2026},
date = {2026-09-20},
urldate = {2026-09-20},
journal = {Transactions on Machine Learning Research},
abstract = {Vision-Language-Action (VLA) models for autonomous driving receive navigation commands and hazard notices as disconnected text fragments, forcing the model to discover on its own which environmental constraints are relevant to the current maneuver. We introduce Causal Scene Narration (CSN), which restructures VLA text inputs through intent-constraint alignment, quantitative grounding, and structured separation, at inference time with zero GPU cost. We additionally evaluate runtime supervision and training-time preference alignment as experimental conditions rather than as contributions. A multi-town CARLA evaluation (16 routes, 8 towns},
keywords = {},
pubstate = {published},
tppubtype = {article}
}
@article{García2026,
title = {Implementation and Evaluation of Late Stage Cooperative Multi-Object Tracking in Urban Scenarios},
author = {Mikel García and Ehsan Javanmardi and Manabu Tsukada and Marcos Nieto and Naiara Aginako and Oihana Otaegui},
doi = {10.1109/TVT.2026.3718064},
year = {2026},
date = {2026-07-27},
urldate = {2026-07-27},
journal = {IEEE Transactions on Vehicular Technology},
abstract = {Future mobility based on Cooperative Intelligent Transport Systems (C-ITS) will allow Vehicle-to-Everything (V2X) communications to exchange information with their surrounding infrastructure and traffic participants. Cooperative Perception (CP) extends the sensing capabilities of each Intelligent Transport System Station (ITS-S) by exchanging standardized data such as Collective Perception Messages (CPM). An example is Cooperative Perception Services (CPS), which extend the sensing capabilities of C-ITS by exchanging standardised perception data. The challenge is to efficiently and robustly fuse received data with own data, accounting for the communication and processing latencies. In this work, we implement a Cooperative Multi Object Tracker (C-MOT) for CPS that fuses its local perception information with the information received from multiple surrounding ITS-S via V2X. Specifically, our method leverages object positions from standardized ETSI messages, including Cooperative Awareness Message (CAM) and cooperative perception data from CPMs. We compare four different association strategies and evaluate the proposed C-MOT in simulations across multiple scenario configurations. Comparing the results obtained by using only local perception data against the proposed C-MOT shows improvements of up to 60% in accuracy while also obtaining more precise positions of the tracks in certain scenarios.},
keywords = {},
pubstate = {published},
tppubtype = {article}
}
@article{Zhou2026c,
title = {CLIFF: A Multi-Modal Remote Sensing Model for Geological Hazard Monitoring Based on Bitemporal UAV Images},
author = {Quanxi Zhou and Qianxiao Su and Xinran Wei and Wencan Mao and Yili Ren and Yunfei Chen and Jianzhong Bi and Mingjun Zhao and Manabu Tsukada},
doi = {10.3390/rs18142432},
year = {2026},
date = {2026-07-22},
urldate = {2026-07-18},
journal = {Remote Sensing},
volume = {18},
number = {2432},
issue = {14},
abstract = {UAV-based remote sensing excels in rapid response, high timeliness, simple operation, and high degrees of automation, and has been widely applied for geological hazard monitoring. Deep learning methods based on unitemporal UAV images can only analyze the static appearance of a scene, while bitemporal change detection can capture the dynamic evolution of hazards; however, due to diverse geological landforms and topography, environmental noises such as vegetation cover, and dynamic weather conditions, change detection of geological hazards from UAV images based on traditional deep learning technology is not always effective. Therefore, there is an urgent need to utilize large vision-language models (LVLMs) to further improve the accuracy and robustness of the change detection model. Motivated by this, this paper proposes a novel remote sensing model for geological hazard monitoring, referred to as CLIFF (CLIP-BIT-EfficientNet), based on the multi-modal LVLM Contrastive Language-Image Pre-training (CLIP), the change detection network Bitemporal Image Transformer (BIT), and the classification network EfficientNet, along with corresponding datasets and model fine-tuning strategies. The proposed transfer fusion module bridges the CLIFF and BIT networks by aligning their feature distributions and dimensions, allowing the general knowledge of the LVLM and the task-specific knowledge of the learnable branch to reinforce each other. Furthermore, this integrated pipeline addresses the scarcity of labeled hazard data by allowing the BIT to train on larger public datasets, while fine-tuning EfficientNet on smaller hazard-classification datasets within the change area, making the approach more efficient and reliable than direct classification methods. Experimental results show that the proposed CLIFF algorithm outperforms state-of-the-art deep learning algorithms such as LightCDNet and ChangeFormer, with an IoU of 75.74% and an F1 score of 0.8689 for change detection. Meanwhile, CLIFF has an overall accuracy rate of 86.89% in identifying geological hazards along gas pipelines, such as crude oil spills, collapses, landslides, and floods, with per-class accuracies of 87.32% and 86.17% for crude oil spills and landslides, respectively.},
keywords = {},
pubstate = {published},
tppubtype = {article}
}
@inproceedings{Chauhan2026b,
title = {Don't Worry, Just Follow Me: Prototyping and In-the-Wild Evaluation of Smart Pole Interaction Unit with Mobility},
author = {Vishal Chauhan and Anubhav Anubhav and Mark Colley and Chia-Ming Chang and Xinyue Gui and Ding Xia and Ehsan Javanmardi and Takeo Igarashi and Kantaro Fujiwara and Manabu Tsukada},
url = {https://youtu.be/PLmCgmTwsHQ},
doi = {10.1145/3772318.3790882},
year = {2026},
date = {2026-04-13},
urldate = {2026-04-13},
booktitle = {ACM CHI conference on Human Factors in Computing Systems 2026},
address = {Barcelona, Spain},
abstract = {Pedestrian–automated vehicle(AV) encounters in shared spaces often involve hesitation and ambiguity. Vehicle-mounted external human–machine interfaces(eHMIs) can help, but obscured or poorly timed communications create significant challenges. To address this, we present a mobile smart pole interaction unit(SPIU) with integrated cameras and LED displays, designed as a pedestrian-side system to deliver explicit cues(``WALK,'' ``STOP''). An in-the-wild evaluation of the SPIU(N=21) using a four-factor analysis (CarBehavior, Mobility, eHMI, SPIU) showed that the SPIU improved understandability, trust, and perceived safety, and reduced workload compared with the baseline, with a combination(eHMI+SPIU) yielding the strongest results. Beyond these quantitative benefits, participants appreciated the mobility of the SPIU for its ``clear'' and ``easy to decide'' mediation. This work contributes to(1) a design and deployment framework for a mobile SPIU and(2) an in-the-wild evaluation protocol for pedestrian–AV interactions in nonsignalized spaces. Our work sparks discussions on real world evaluations involving detailed vehicle kinematics and accessible multimodality(e.g., audio), focusing on the role of personal robots as user-side eHMIs.},
note = {Honourable Mention Award},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
@inproceedings{Gui2026,
title = {Peeking Ahead of the Field Study: Exploring VLM Personas as Support Tools for Embodied Studies in HCI},
author = {Xinyue Gui and Ding Xia and Mark Colley and Yuan Li and Vishal Chauhan and Anubhav Anubhav and Zhongyi Zhou and Ehsan Javanmardi and Stela Hanbyeol Seo and Chia-Ming Chang and Manabu Tsukada and Takeo Igarashi},
url = {https://arxiv.org/abs/2602.16157
https://youtu.be/PORfzWr2v5c},
doi = {10.1145/3772318.3790537},
year = {2026},
date = {2026-04-13},
urldate = {2026-04-13},
booktitle = {ACM CHI conference on Human Factors in Computing Systems 2026},
address = {Barcelona, Spain},
abstract = {Field studies are irreplaceable but costly, time-consuming, and error-prone, which need careful preparation. Inspired by rapid-prototyping in manufacturing, we propose a fast, low-cost evaluation method using Vision-Language Model (VLM) personas to simulate outcomes comparable to field results. While LLMs show human-like reasoning and language capabilities, autonomous vehicle (AV)-pedestrian interaction requires spatial awareness, emotional empathy, and behavioral generation. This raises our research question: To what extent can VLM personas mimic human responses in field studies? We conducted parallel studies: 1) one real-world study with 20 participants, and 2) one video-study using 20 VLM personas, both on a street-crossing task. We compared their responses and interviewed five HCI researchers on potential applications. Results show that VLM personas mimic human response patterns (e.g., average crossing times of 5.25 s vs. 5.07 s) lack the behavioral variability and depth. They show promise for formative studies, field study preparation, and human data augmentation.},
note = {Honourable Mention Award},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
@workshop{Hu2025,
title = {A Low PAPR Layered Multi-User OTFS Modulation},
author = {Dou Hu and Jin Nakazato and Kazuki Maruta and Omid Abbassi Aghda and Rui Dinis and Manabu Tsukada},
year = {2025},
date = {2025-06-17},
urldate = {2025-06-17},
booktitle = {AI-Driven Connectivity for Vehicular and Wireless Networks in VTC2025-Spring},
address = {Oslo, Norway},
abstract = {In modern communication systems, meeting the growing demand for high-capacity transmission requires developing efficient and robust modulation techniques. To address this, we propose a low-PAPR page-style Orthogonal Time Frequency Space (OTFS) modulation framework that enhances communication capacity while maintaining a low peak-to-average power ratio (PAPR). The proposed design introduces a novel pilot signal placement and analysis method, improving channel estimation accuracy and system performance in high-mobility multi-user scenarios. This paper provides an overview of recent advancements in OTFS-based multi-user communication systems, emphasizing their contributions to enhancing spectral efficiency, reliability, and robustness. Through extensive simulations, we demonstrate the effectiveness of the proposed framework in achieving superior BER performance, improved interference mitigation, and robust transmission capabilities compared to traditional methods, validating its suitability for next-generation communication networks.},
howpublished = {Workshop on AI-Driven Connectivity for Vehicular and Wireless Networks in VTC2025-Spring},
note = {IEEE VTS Tokyo/Japan Chapter 2025 Young Researcher's Encouragement Award},
keywords = {},
pubstate = {published},
tppubtype = {workshop}
}
@inproceedings{Gong2026b,
title = {CARE: Camera-Residual Reserves for First Sightings in Adaptive LiDAR Sensing},
author = {Jiachen Gong and Yun Li and Ehsan Javanmardi and Wencan Mao and Manabu Tsukada},
year = {2026},
date = {2026-12-14},
urldate = {2026-12-14},
booktitle = {The 18th Asian Conference on Computer Vision (ACCV 2026)},
address = {Osaka, Japan},
abstract = {Adaptive LiDAR scanning, which concentrates a limited sensing budget on informative regions of interest based on past object tracks, is becoming a key enabler in autonomous driving by lowering data volume while maintaining detection accuracy. However, existing scanning policies face three key challenges. First, history-driven approaches depend heavily on past object tracks, leading to delayed or missed detection of unseen objects. Second, methods leveraging random or uniform sampling outside the predicted regions have no awareness of where new objects appear. Third, camera-guided alternatives spend their budget on all camera detections, resampling objects that are already covered, which costs overall recall in crowded scenes and detection range when budgets are scarce. To address these limitations, this paper introduces the CAmera-REsidual reserve (CARE), a training-free allocation rule that reserves part of a fixed ray budget for the directions of current camera detections that the track forecasts cannot explain, while the remaining budget follows the base history policy and unused reserve returns to a shared random floor. The paper makes three key contributions: First, a leakage-free ray-budget evaluation on nuScenes (150 scenes, 4,148 events) that measures the first-sighting loss of history-driven scanning, with a strict-causal variant using the preceding keyframe. Second, CARE raises first-sighting recall by 5.2, 5.2, and 4.3 points at 10%, 20%, and 35% budgets over the history policy with paired intervals excluding zero; the camera cue drives this gain, and the first-sighting versus overall trade-off is reported openly as a budget-dependent Pareto choice. Third, a safety-bounded forgetting module that releases budget from receding or static tracks beyond a speed-dependent guard distance; at tight budgets forgetting without the guard significantly harms near-field recall, and the guard is what keeps forgetting safe at the tightest budget. The pipeline runs end to end on a real vehicle and, in a closed-loop simulation, detects an occluded pedestrian earlier and brakes more reliably than history-driven scanning.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
@inproceedings{Chi2026b,
title = {Blockage-Aware Non-stationary Dynamic Bandit for User Association in mmWave V2X Networks},
author = {Weiqi Chi and Manabu Tsukada},
year = {2026},
date = {2026-12-07},
urldate = {2026-12-07},
booktitle = {IEEE Global Communications Conference (GLOBECOM 2026)},
address = {Macau, China},
abstract = {In millimeter-wave (mmWave) vehicular networks, dense base station (BS) deployments and dynamic blockages introduce severe non-stationarity into the user association (UA), posing a critical mobility management challenge that hinders rapid and effective UA decisions. Traditional Multi-Armed Bandit (MAB) frameworks assume stationary reward distributions and fail to handle the rapid context-reward mapping shifts caused by vehicle mobility and transient blockages. To address this, we propose Blockage-Aware Non-stationary Dynamic Bandit (BAND), a fully distributed, Channel state information (CSI)-free mobility management framework for mmWave vehicular networks, formulating UA as a non-stationary contextual bandit problem and enables online adaptive optimization without requiring central coordination or offline training. BAND employs a cumulative sum-based change detection (CUSUM-CD) to dynamically narrow the active BS set, reducing exploration overhead while tracking reward distribution shifts. Proactive blockage detections suppress transient signal degradation in reward estimation. Simulations demonstrate over 44% regret reduction and up to 27.3% network communication rate improvement over hypercube-based contextual bandit baselines, with robustness validated across varying blockage rates and network configurations.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
@inproceedings{Zhou2026d,
title = {MPDS-SAC: Multi-horizon Post-Decision State Soft Actor-Critic for Air-Ground Collaborative Sensing},
author = {Quanxi Zhou and Wencan Mao and Yunfei Chen and Junru Li and Jiachen Gong and Kensuke Fukuda and Manabu Tsukada},
year = {2026},
date = {2026-12-01},
urldate = {2026-12-01},
booktitle = {21st Asian Internet Engineering Conference (AINTEC 2026)},
address = {Taipei, Taiwan},
abstract = {Air-ground collaborative sensing, which utilizes unmanned aerial vehicles (UAVs) to collect data from ground wireless sensors, facilitates smart-city monitoring benefiting from mobility, scalability, and fast responses. However, existing model-free trajectory-planning policies learn action consequences purely from sampled experience, without exploiting environmental and scenario-specific patterns, leading to slow convergence and short-sighted decision-making. This paper proposes a Multi-horizon Post-Decision State Soft Actor-Critic (MPDS-SAC) algorithm for jointly optimizing multi-UAV trajectories in air-ground collaborative sensing. Within MPDS-SAC, SAC provides the deep reinforcement learning (DRL) backbone for trajectory optimization, while MPDS exploits deterministic transition rules and available observations to analytically predict the states resulting from two successive decisions without additional environment interactions. These additional post-decision states provide the critic with richer training signals, improving sample efficiency and value-estimation accuracy. Experiments on a real-world urban topology show gains over state-of-the-art DRL baselines in reward, convergence speed, and stability, with consistent improvements in information freshness and uplink quality as well as comparable sensor coverage.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
@inproceedings{Li2026e,
title = {GeoFlex: Geographic-Prior Flexible Adaptation of Per-Domain Diffusion Trajectory Planners to Held-Out Deployment Regions},
author = {Yun Li and Ehsan Javanmardi and Simon Thompson and Jiachen Gong and Qunli Zhang and Zifan Zeng and Shiming Liu and Peng Wang and Yidu Zhang and Manabu Tsukada},
year = {2026},
date = {2026-11-09},
urldate = {2026-11-09},
booktitle = {Conference on Robot Learning (CoRL 2026)},
address = {Austin, Texas, USA},
abstract = {Cross-region deployment of a structured multi-domain diffusion planner reduces to a small-data fine-tuning problem rather than a per-scene routing problem. We test eight zero- or low-training routing schemes on three real-world held-out maps under a disjoint-lanelet protocol; none beats a trivial static rule that picks the geographically nearest training domain. A Fano bound and a split-conformal exchangeability rejection (p=0.0035) explain why no scene-feature router can break this static-prior ceiling, and a PAC-Bayes-certified von Mises-Fisher mixture, the strongest principled routing-class baseline, confirms the limit is architectural: any method confined to the linear span of the four per-expert weights is bounded by the static-prior fleet mean (15.85 vs. 13.74 m). Stepping outside this subspace breaks the ceiling. Joint replay, mixing target-region scenes with training scenes at 10:1 during fine-tuning, reaches 4.26 m fleet-mean on disjoint lanelets (-76% vs. frozen substrate) at +0.74 m in-region regression; the recipe replicates across all four nuPlan leave-one-city-out configurations including a -35% Singapore reduction under left-hand-traffic rule shift. As a methodological contribution we introduce variance-collapse forensics: a two-line diagnostic (within-scene K-sample variance plus cross-scene pairwise L2) that unmasks hypernetwork-conditioned LayerNorm and faithful TENT (test-time entropy minimisation) as near-stationary degenerate trajectories whose seemingly-strong fleet means would otherwise overstate the gain by an order of magnitude. The same backbone has passed real-vehicle closed-loop deployment under a production DPO LoRA (joint-replay weights are not yet on-vehicle), where adversarial-aware training lifts peak deceleration 3.4x without losing natural-data comfort.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
@inproceedings{Adhipradhana2026,
title = {DispatchRAG: Grounding Emergency Dispatch Decisions in Real-World Protocols from Traffic Accident Video},
author = {Muhammad Sulthan Adhipradhana and Ehsan Javanmardi and Naren Bao and Manabu Tsukada},
url = {https://arxiv.org/abs/2607.23132},
year = {2026},
date = {2026-11-09},
urldate = {2026-11-09},
booktitle = {2026 Asia Pacific Signal and Information Processing Association Annual Summit and Conference (APSIPA ASC 2026)},
address = {Bangkok, Thailand},
abstract = {Assessing the severity of a traffic accident scenario is important to decide which emergency service to dispatch. Missing an ambulance dispatch on a pedestrian accident is a fatal issue that can lead to death. Recently, Vision-Language Models (VLMs) have been a promising tool for accident reasoning, yet many VLMs are not grounded in real-life accident response protocols, making them not usable in accident severity assessment off-the-shelf. We introduced DispatchRAG, an accident assessor and dispatcher framework grounded in real-life Japanese traffic-accident response protocols, designed to enhance VLMs to generate an appropriate emergency response during an emergency scenario. Utilizing a RAG-based retrieval mechanism to retrieve the most relevant accident protocol and an LLM-powered reasoner to suggest the most proper response. To support evaluation, we introduce Accident Dispatch Dataset, a comprehensive dataset of accident assessment and emergency response according to Japanese accident response protocols adapted from the MM-AU dataset. We validate our framework on the Accident Dispatch Dataset, showing strong performance across various accident scenarios compared to the baseline VLM, pointing toward integration in autonomous vehicles that can automatically report both their own and nearby accidents.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
@inproceedings{Orsholits2026,
title = {GP-02: A Sub-50 g Head-Mounted RTK-GNSS/IMU/Barometer Pose Estimator with On-Board GNSS-Denied Recovery},
author = {Alex Orsholits and Manabu Tsukada},
year = {2026},
date = {2026-11-06},
urldate = {2026-11-06},
booktitle = {The 4th Annual IEEE International Conference on Metaverse Computing, Networking, and Applications (MetaCom 2026)},
address = {Xi'an, China},
abstract = {Georeferenced head pose connects locally stable headset tracking to outdoor mixed-reality content, yet headset odometry ordinarily remains in a local frame and wearable GNSS provides position rather than head-referenced 6-DOF pose. GP-02 addresses this gap with a self-contained, 45.8 g head-worn device that fuses RTK-GNSS, a consumer IMU, and a barometer on an ESP32-S3. It emits georeferenced pose at a nominal 100 Hz without a phone, single-board computer, or offline processing. Because head orientation changes independently of walking direction, a selective-yaw estimator observes the head-to-travel offset from RTK course over ground and maintains the relationship during GNSS denial. Four continuous walks covering 7.26 km and 72.1 min across Tokyo characterise the system under progressively restricted sky visibility. Across the three runs with healthy orientation measurements, head and travel direction differed by more than 15 degrees for 65-89 percent of moving fixed-RTK observations. The estimated trajectories follow street geometry in open and moderately obstructed environments and continue through short GNSS outages. In the dense Nihonbashi canyon, ambiguity-float fixes and an IMU orientation fault degrade the horizontal trajectory, while barometric fusion suppresses raw vertical excursions of hundreds of metres. The results establish the operating envelope of a standalone absolute-pose wearable and identify the complementary role of headset visual-inertial odometry in dense urban environments.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}

🇫🇷 Paris leg of our European tour!
On Oct 2 we visited VEDECOM in Versailles to meet the French team of our Japan–Europe collaboration on cooperative mobility, then headed to CentraleSupélec on the Paris-Saclay campus for an afternoon of in-depth research discussions. 🚗📡
Oct 3 was a reunion with Thierry Ernst, a long-time collaborator since the INRIA days of our ITS research. Great conversations, great food, and new ideas for working together. 🤝🥐
Merci beaucoup to everyone who welcomed us!
10月 6
A day of research, discovery, and great conversations at THI in Ingolstadt! 🚗🔬🇩🇪
Prof. Manabu Tsukada shared our lab’s research on connected and automated driving and explored the CARISSMA facilities, Car2X lab, and vehicle simulator.
Many thanks to Andreas Festag and the THI team for the warm welcome and fascinating lab tours—and to Andreas for showing us around Ingolstadt! 🤝
📸 Photos courtesy of Andreas Festag
📍 Ingolstadt, Germany | September 30, 2026
10月 1
Research, shared curiosity, and new connections in St.Gallen! 🇨🇭🤝
Our JST CREST Internet of Realities project joined the University of St.Gallen’s Interactions Research Group for a workshop on computing and human realities—with a visit to the Abbey Library and dinner together the following day. 📚🍽️
10月 1
🇮🇹 Four days at IEEE ITSC 2026 in Naples!
The 29th edition filled the Stazione Marittima on the port with about 1,100 researchers, 16 parallel rooms and 831 presentations. Three papers from our lab are in the proceedings, and Prof. Tsukada gave a keynote at the DriveX workshop on agentic AI for cooperative autonomous driving, plus an invited talk at W19 on bridging ground vehicles and aerospace systems.
And then the gala dinner happened, under the Neapolitan stars on the coast at Bacoli 💃🕺
#ITSC2026 #IEEEITSC #TLab #UTokyo #UniversityOfTokyo 東京大学 塚田研 Naples V2X AutonomousDriving
9月 20
🇸🇪 ECCV 2026 in Malmö! Our lab presented HERO: Heterogeneous Evidential Robust Object-Level Collaborative Perception, a way for vehicles with different sensors and detectors to share what they see without sharing huge feature maps.
By attaching evidential statistics to each detected box, HERO matches state-of-the-art feature-level fusion while cutting communication bandwidth by over 1000x, and it stays robust even under pose error and latency. 🚗📡
Great talks, great people, and a beautiful city. Thanks to everyone who stopped by! 🎉
#ECCV2026 #ECCV #TLab #UTokyo #UniversityOfTokyo 東京大学 塚田研 CollaborativePerception AutonomousDriving ComputerVision Malmö
9月 14
Real signals. Real crosswalks. Real rain. 🌧️
Three days of V2X hands-on at our ITS R&R experimental field in Kashiwa — the spin-off of the JSAE Automotive AI Challenge 2026, organized together with UTokyo UTmobI. The teams brought their karts, we brought the roadside units, and the weather brought the difficulty setting 🏎️⚡
Presentations and demo runs on day one, roadside debugging in between, and laptops still open long after sunset. That’s what a field experiment actually looks like 💜
#TLab #UTokyo #UniversityOfTokyo #東京大学 #塚田研 UTmobI JSAE AIChallenge2026 自動運転AIチャレンジ V2X AutonomousDriving ITS 柏キャンパス 自動運転
9月 12
That’s a wrap on CIV Summer School 2026 🌊🚗
Five days in Miyazaki with 38 participants from 19 institutions (11+ nationalities!) for the 6th edition of the Summer School on Cooperative Interacting Vehicles, held in Asia for the first time.
🎓 14 lectures
📌 16 posters
🤖 Hands-on with LiDAR and a real rover
💻 A data hackathon on fleet recordings from Kashiwa and Reims
🍢 And plenty of Miyazaki in between
Thank you to everyone who came, taught, asked, and stayed up late. See you at CIV 2027! 👋
Co-organized by The University of Tokyo, Mines Paris–PSL, Karlsruhe Institute of Technology, UC Berkeley and the German University in Cairo, with support from the IEEE Intelligent Transportation Systems Society.
#CIVSummerSchool #CIV2026 #CooperativeInteractingVehicles #AutonomousDriving #V2X SummerSchool Miyazaki Seagaia IEEEITSS TLab UTokyo UniversityOfTokyo 東京大学 塚田研
9月 4
Our joint summer retreat with Esaki Lab and Ochiai Lab in Nagano! 🏔️
Three labs, three days (July 31 – Aug 2), and nearly 30 of us came together for research presentations, deep discussions, and plenty of fun in between. 📚🤝
Great talks, great food, and great memories — already looking forward to the next one! 🎉
#TLab #UTokyo #UniversityOfTokyo #LabRetreat #Nagano
8月 2
Three guests, three countries, one lab. 🇰🇷🇫🇷🇯🇵
Prof. JaeSeung Song and Prof. Jong-Hyouk Lee (Sejong University) and Prof. Jean-Marie Bonnin (IMT Atlantique) joined us at UTokyo on July 28 to talk AI, security and future mobility networks — then dinner. Some collaborations start with a whiteboard, some with a good meal. 🍻
#UTokyo #東京大学 #塚田研究室 #SejongUniversity #IMTAtlantique 国際共同研究 AI 6G
7月 29
🇹🇭 TLab @ MIWA 2026 – Bangkok!
Our team joined MIWA 2026 — Mobility Interaction for a World in Action — at Chulalongkorn University in Bangkok.
Prof. Manabu Tsukada delivered a keynote talk, “Cooperative Intelligence for Autonomous Driving: From V2X to Human-Agent Interaction,” and moderated the session “AI Shaping the Future of Mobility Systems.”
Prof. Ehsan Javanmardi also attended the event together with our PhD students, Yun Li and Yu Asabe. Yun presented her work on trustworthy AI for autonomous driving, while Yu shared his research on cooperative maneuver coordination.
From inspiring discussions on AI, V2X, and future mobility to the technical tour at Thailand’s CAV Sandbox, it was a fantastic opportunity to exchange ideas with researchers and industry leaders from across Asia.
Thank you to the organizers and everyone we met in Bangkok!
7月 23
住所:
〒113-8657 東京都文京区弥生1-1-1 東京大学大学院情報理工学系研究科創造情報学専攻 I-REF棟4F
〒113-8656 東京都文京区本郷7-3-1 東京大学 工学部2号館 9階91B1号室
メール: