
Causal Scene Narration: Inference-Time Text Restructuring for Vision-Language-Action Driving
Transactions on Machine Learning Research, 2026年9月20日
3行要約
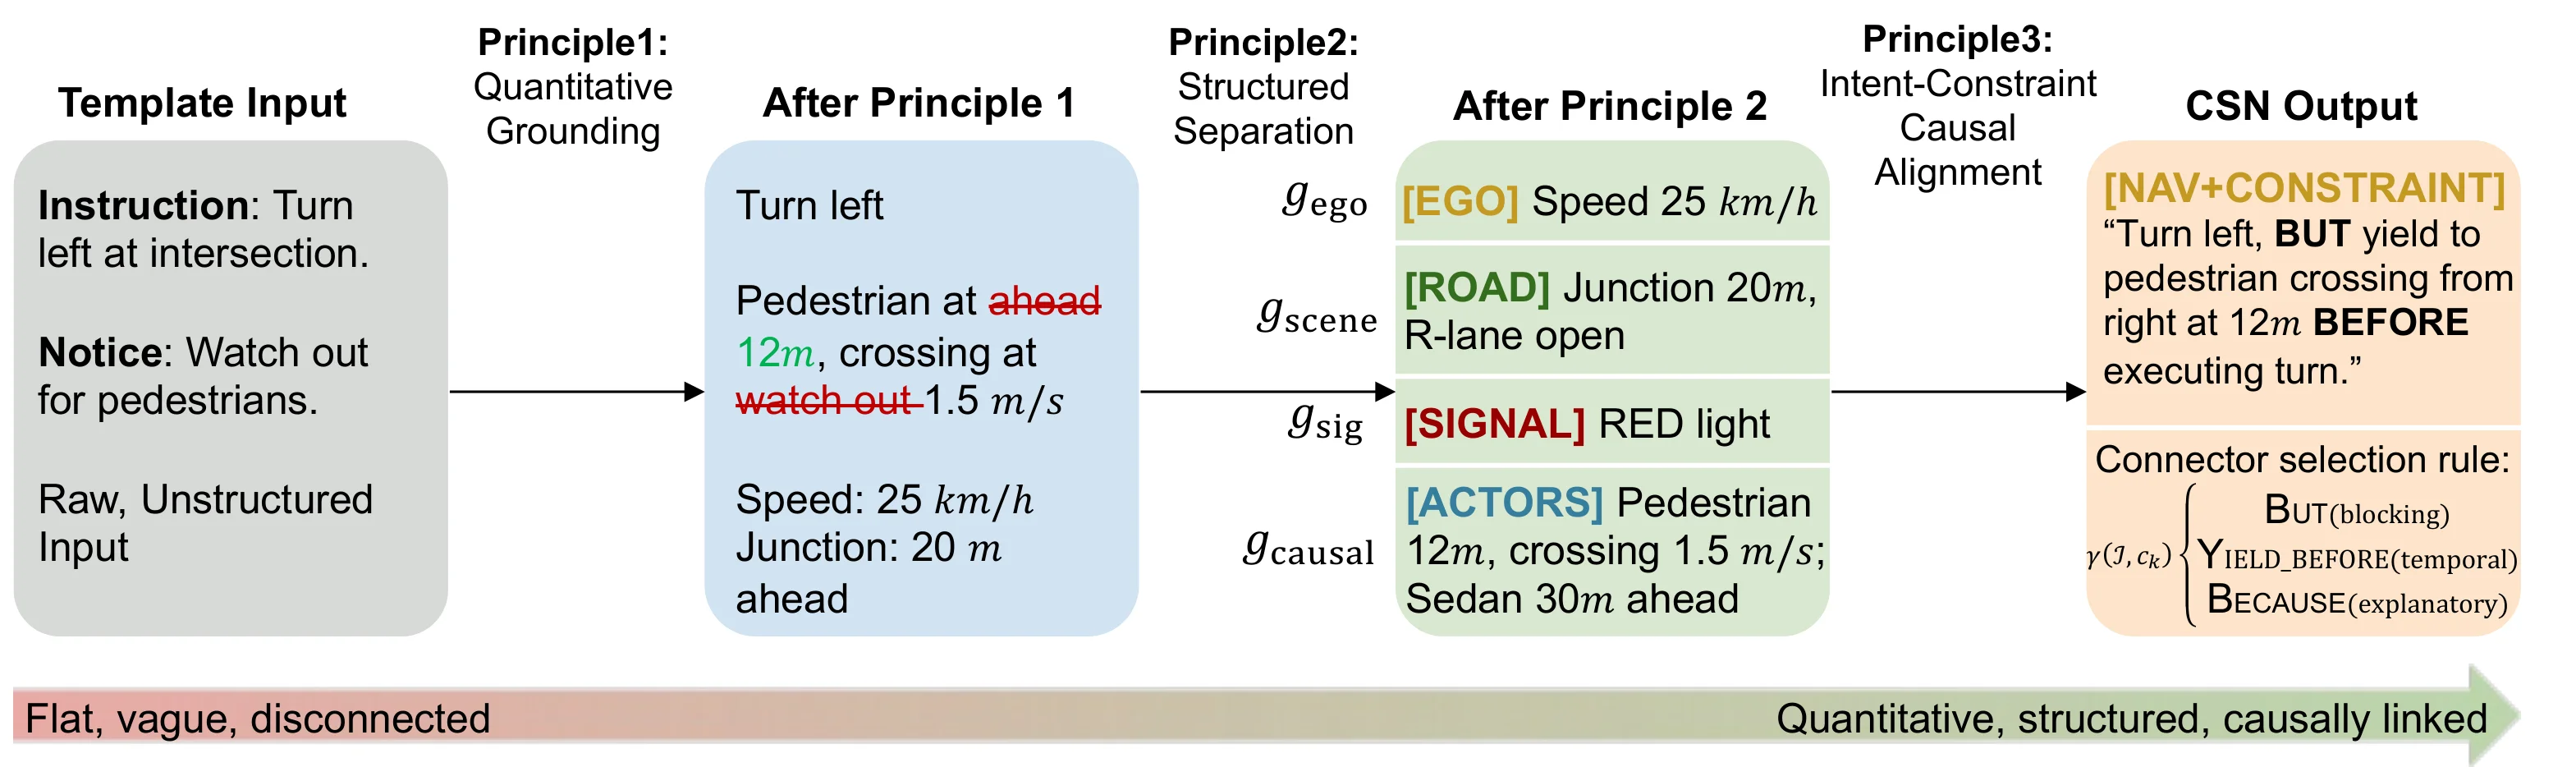
- Causal Scene Narrationは運転モデルに渡す文章を推論時に組み直す。
- 予定する動作と周囲の危険などの制約を明示的に結び付け、定量的な場面情報を記述する。
- CARLAの閉ループ評価で運転スコアが向上し、除去実験で因果構造自体の寄与を確認した。
論文の図
アブストラクト(原文)
Vision-Language-Action (VLA) models for autonomous driving receive navigation commands and hazard notices as disconnected text fragments, forcing the model to discover on its own which environmental constraints are relevant to the current maneuver. We introduce Causal Scene Narration (CSN), which restructures VLA text inputs through intent-constraint alignment, quantitative grounding, and structured separation, at inference time with zero GPU cost. We additionally evaluate runtime supervision and training-time preference alignment as experimental conditions rather than as contributions. A multi-town CARLA evaluation (16 routes, 8 towns
引用方法
Y. Li, Y. Zhang, S. Thompson, E. Javanmardi, and M. Tsukada, “Causal Scene Narration: Inference-Time Text Restructuring for Vision-Language-Action Driving,” Transactions on Machine Learning Research, 2026.
BibTeX
@article{Li2026g,
  title         = {Causal Scene Narration: Inference-Time Text Restructuring for Vision-Language-Action Driving},
  author        = {Yun Li and Yidu Zhang and Simon Thompson and Ehsan Javanmardi and Manabu Tsukada},
  url           = {https://arxiv.org/abs/2604.01723},
  year          = {2026},
  date          = {2026-09-20},
  urldate       = {2026-09-20},
  journal       = {Transactions on Machine Learning Research},
  abstract      = {Vision-Language-Action (VLA) models for autonomous driving receive navigation commands and hazard notices as disconnected text fragments, forcing the model to discover on its own which environmental constraints are relevant to the current maneuver. We introduce Causal Scene Narration (CSN), which restructures VLA text inputs through intent-constraint alignment, quantitative grounding, and structured separation, at inference time with zero GPU cost. We additionally evaluate runtime supervision and training-time preference alignment as experimental conditions rather than as contributions. A multi-town CARLA evaluation (16 routes, 8 towns},
  keywords      = {Other},
  pubstate      = {published},
  tppubtype     = {article}
}