
A Synthetic Benchmark for Collaborative 3D Semantic Occupancy Prediction in V2X-Enabled Autonomous Driving
IEEE International Conference on Robotics & Automation (ICRA 2026), Vienna, Austria, 2026年6月1日
3行要約
- 既存協調知覚研究は 3D bbox 中心で semantic occupancy prediction には専用データセットがなかった。
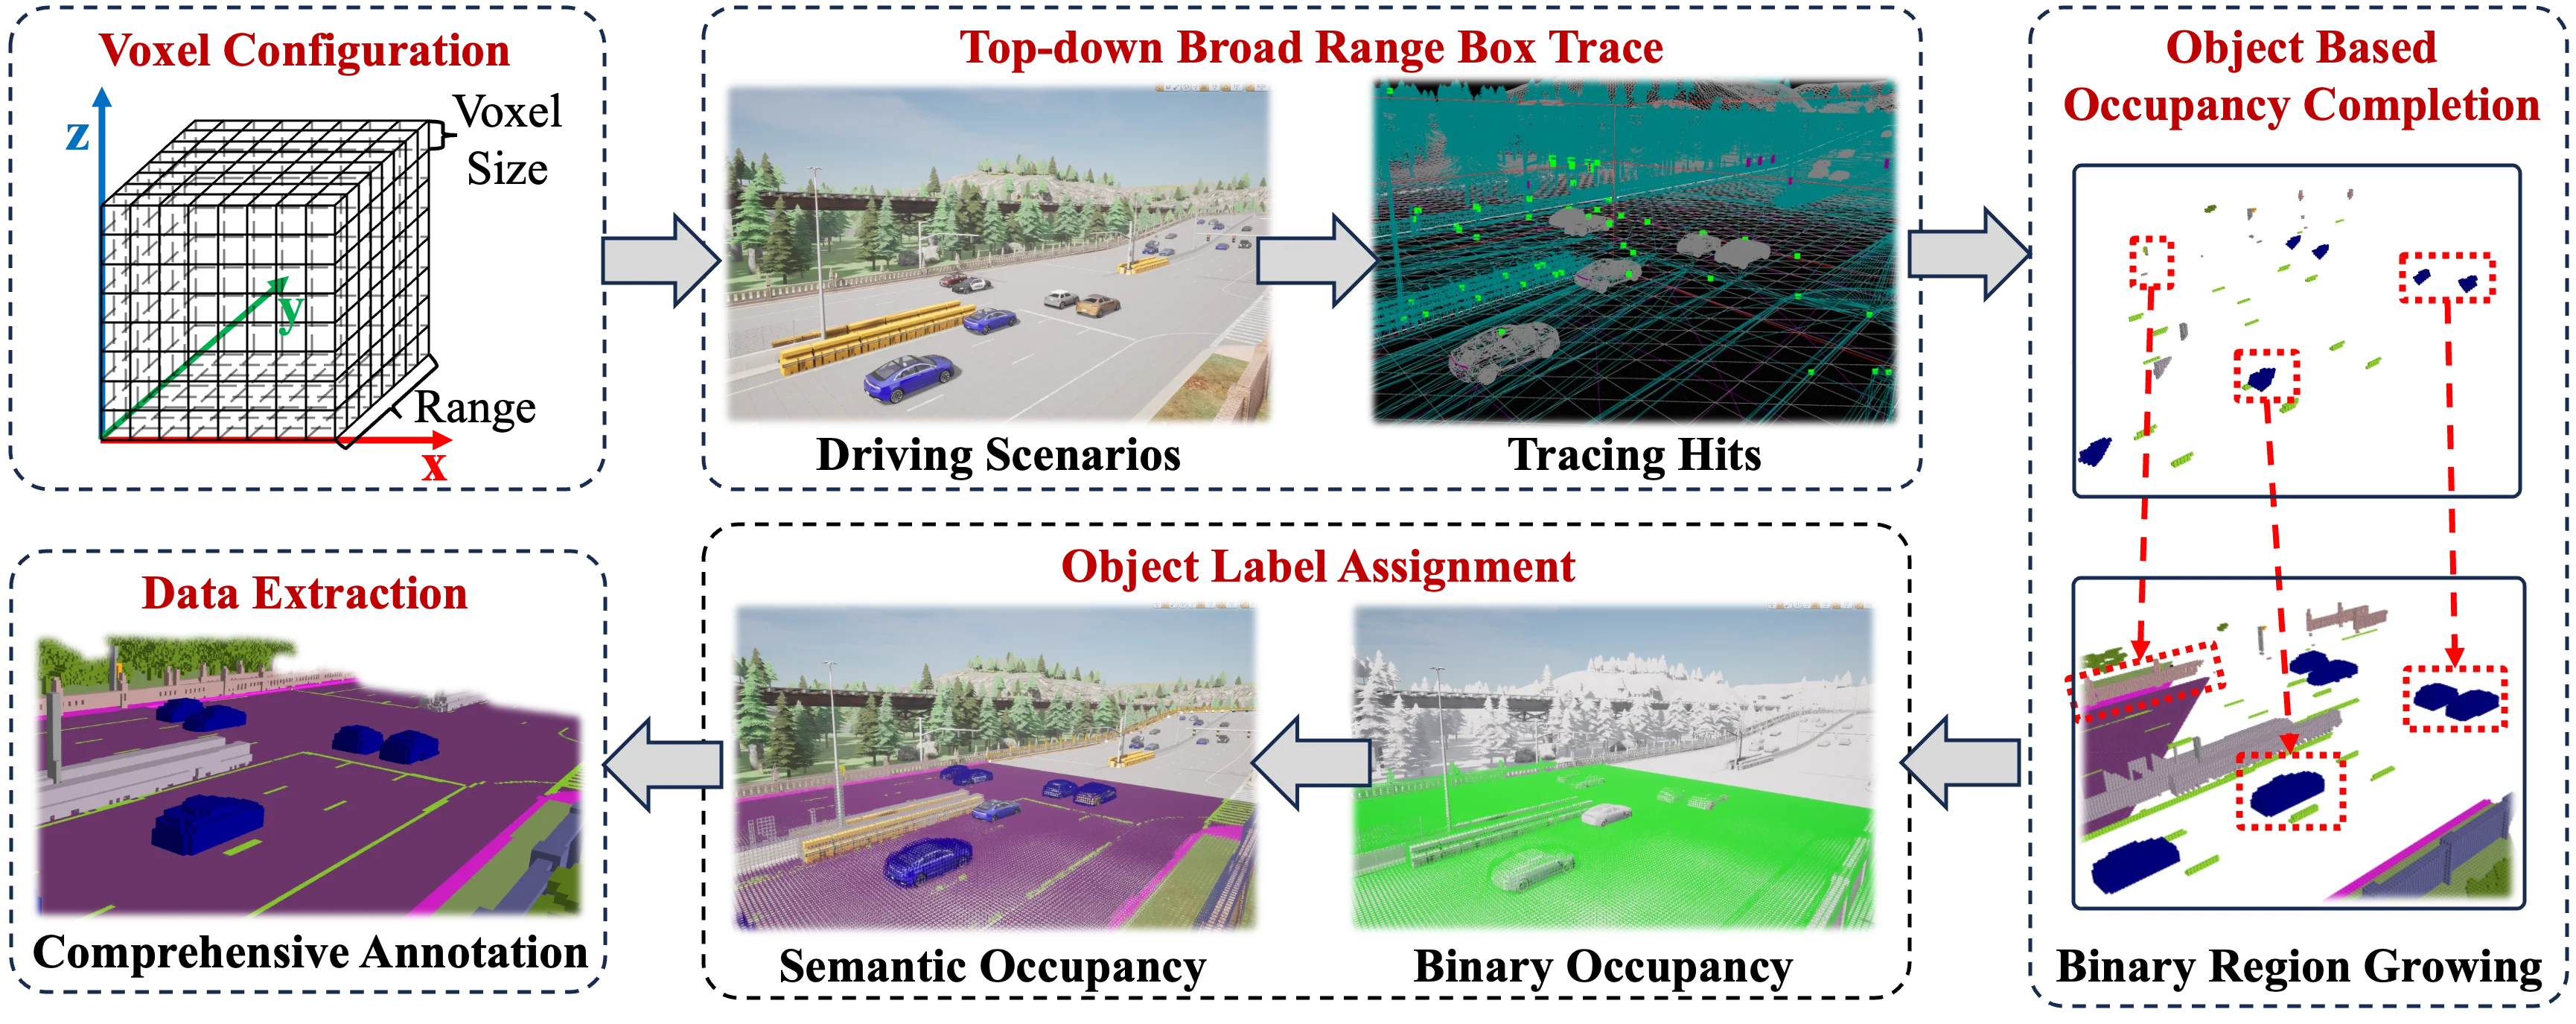
- CARLA に高解像度 semantic voxel sensor を実装、OPV2V の V2V シナリオに沿った Co3SOP データセットを公開。
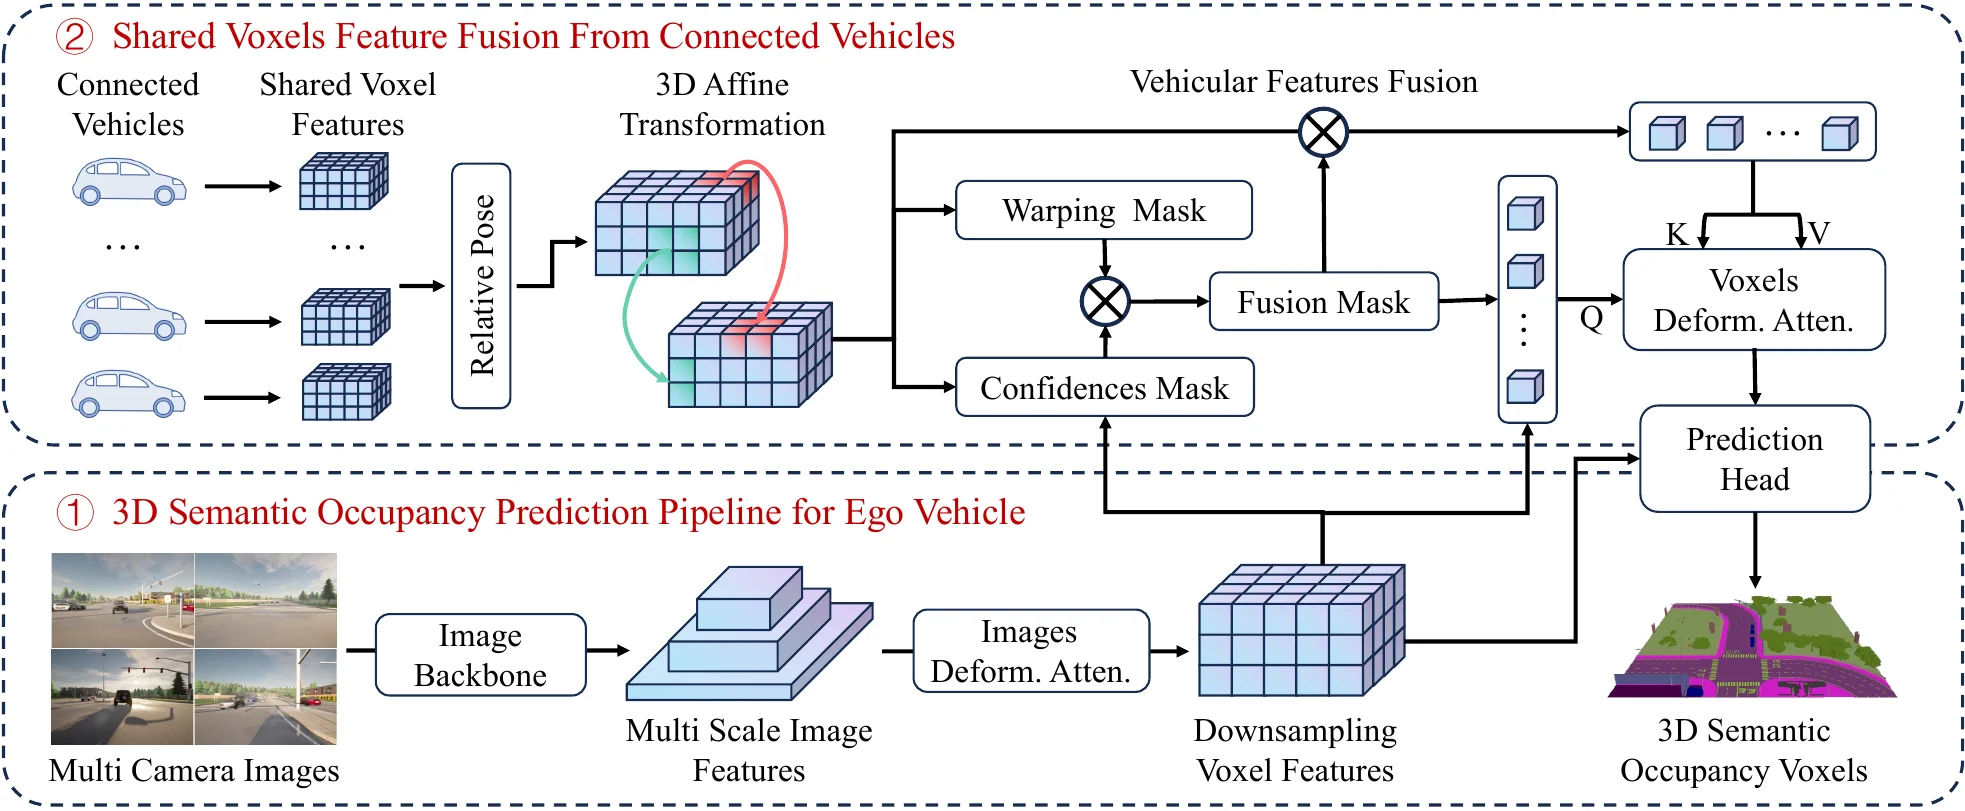
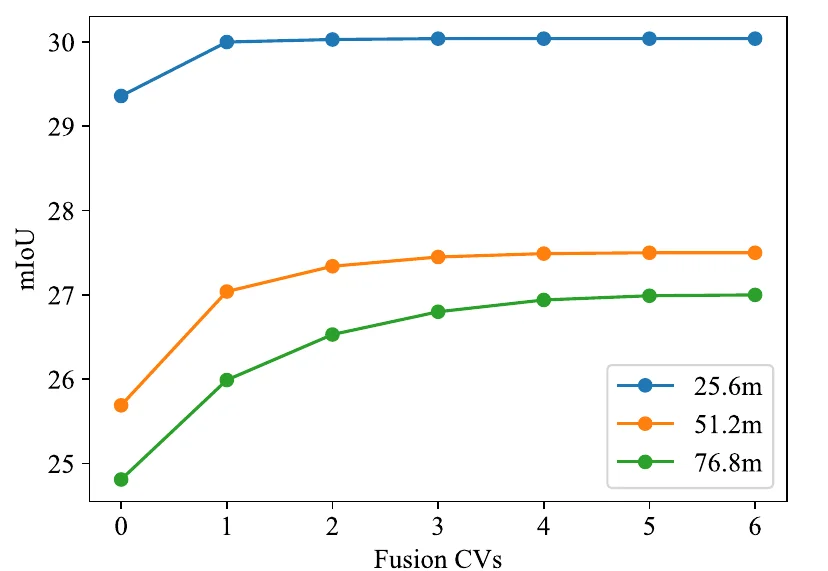
- ベースライン (Co3SOP-Base) で inter-agent feature fusion (空間整列 + attention) → 協調が常にプラス、範囲が広がるほど効果が増大。
論文の図
アブストラクト(原文)
3D semantic occupancy prediction is an emerging perception paradigm in autonomous driving, providing a voxel-level representation of both geometric details and semantic categories. However, its effectiveness is inherently constrained in single-vehicle setups by occlusions, restricted sensor range, and narrow viewpoints. To address these limitations, collaborative perception enables the exchange of complementary information, thereby enhancing the completeness and accuracy of predictions. Despite its potential, research on collaborative 3D semantic occupancy prediction is hindered by the lack of dedicated datasets. To bridge this gap, we design a high-resolution semantic voxel sensor in CARLA to produce dense and comprehensive annotations. We further develop a baseline model that performs inter-agent feature fusion via spatial alignment and attention aggregation. In addition, we establish benchmarks with varying prediction ranges designed to systematically assess the impact of spatial extent on collaborative prediction. Experimental results demonstrate the superior performance of our baseline, with increasing gains observed as range expands.
動画
コード · データ
関連する研究・ソフトウェア
関連ニュース
引用方法
H. Wu, P. Lin, E. Javanmardi, N. Bao, B. Qian, H. Si, and M. Tsukada, “A Synthetic Benchmark for Collaborative 3D Semantic Occupancy Prediction in V2X-Enabled Autonomous Driving,” in IEEE International Conference on Robotics & Automation (ICRA 2026), Vienna, Austria, 2026.
BibTeX
@inproceedings{Wu2026,
  title         = {A Synthetic Benchmark for Collaborative 3D Semantic Occupancy Prediction in V2X-Enabled Autonomous Driving},
  author        = {Hanlin Wu and Pengfei Lin and Ehsan Javanmardi and Naren Bao and Bo Qian and Hao Si and Manabu Tsukada},
  url           = {https://arxiv.org/abs/2506.17004 https://github.com/tlab-wide/Co3SOP https://youtu.be/VlrqcdkMyn8},
  eprint        = {2506.17004},
  archiveprefix = {arXiv},
  primaryclass  = {cs.CV},
  year          = {2026},
  date          = {2026-06-01},
  urldate       = {2026-06-01},
  booktitle     = {IEEE International Conference on Robotics & Automation (ICRA 2026)},
  address       = {Vienna, Austria},
  abstract      = {3D semantic occupancy prediction is an emerging perception paradigm in autonomous driving, providing a voxel-level representation of both geometric details and semantic categories. However, its effectiveness is inherently constrained in single-vehicle setups by occlusions, restricted sensor range, and narrow viewpoints. To address these limitations, collaborative perception enables the exchange of complementary information, thereby enhancing the completeness and accuracy of predictions. Despite its potential, research on collaborative 3D semantic occupancy prediction is hindered by the lack of dedicated datasets. To bridge this gap, we design a high-resolution semantic voxel sensor in CARLA to produce dense and comprehensive annotations. We further develop a baseline model that performs inter-agent feature fusion via spatial alignment and attention aggregation. In addition, we establish benchmarks with varying prediction ranges designed to systematically assess the impact of spatial extent on collaborative prediction.  Experimental results demonstrate the superior performance of our baseline, with increasing gains observed as range expands.},
  keywords      = {CRONOS, ITS, Software-Data},
  pubstate      = {published},
  tppubtype     = {inproceedings}
}