
Criteria for Reinforcement Learning Suitability in Multi-UAV Precision-Agriculture Coverage: Sensing Cost, Task Structure, and Policy Selection
Master Thesis, Graduate School of Information Science and Technology, The University of Tokyo, 2026年9月30日
3行要約
- 精密灌漑の複数UAVによる観測で、強化学習が有利になる条件を調べる。
- センシング需要、観測窓、方策の表現力の効果を統制実験で切り分けた。
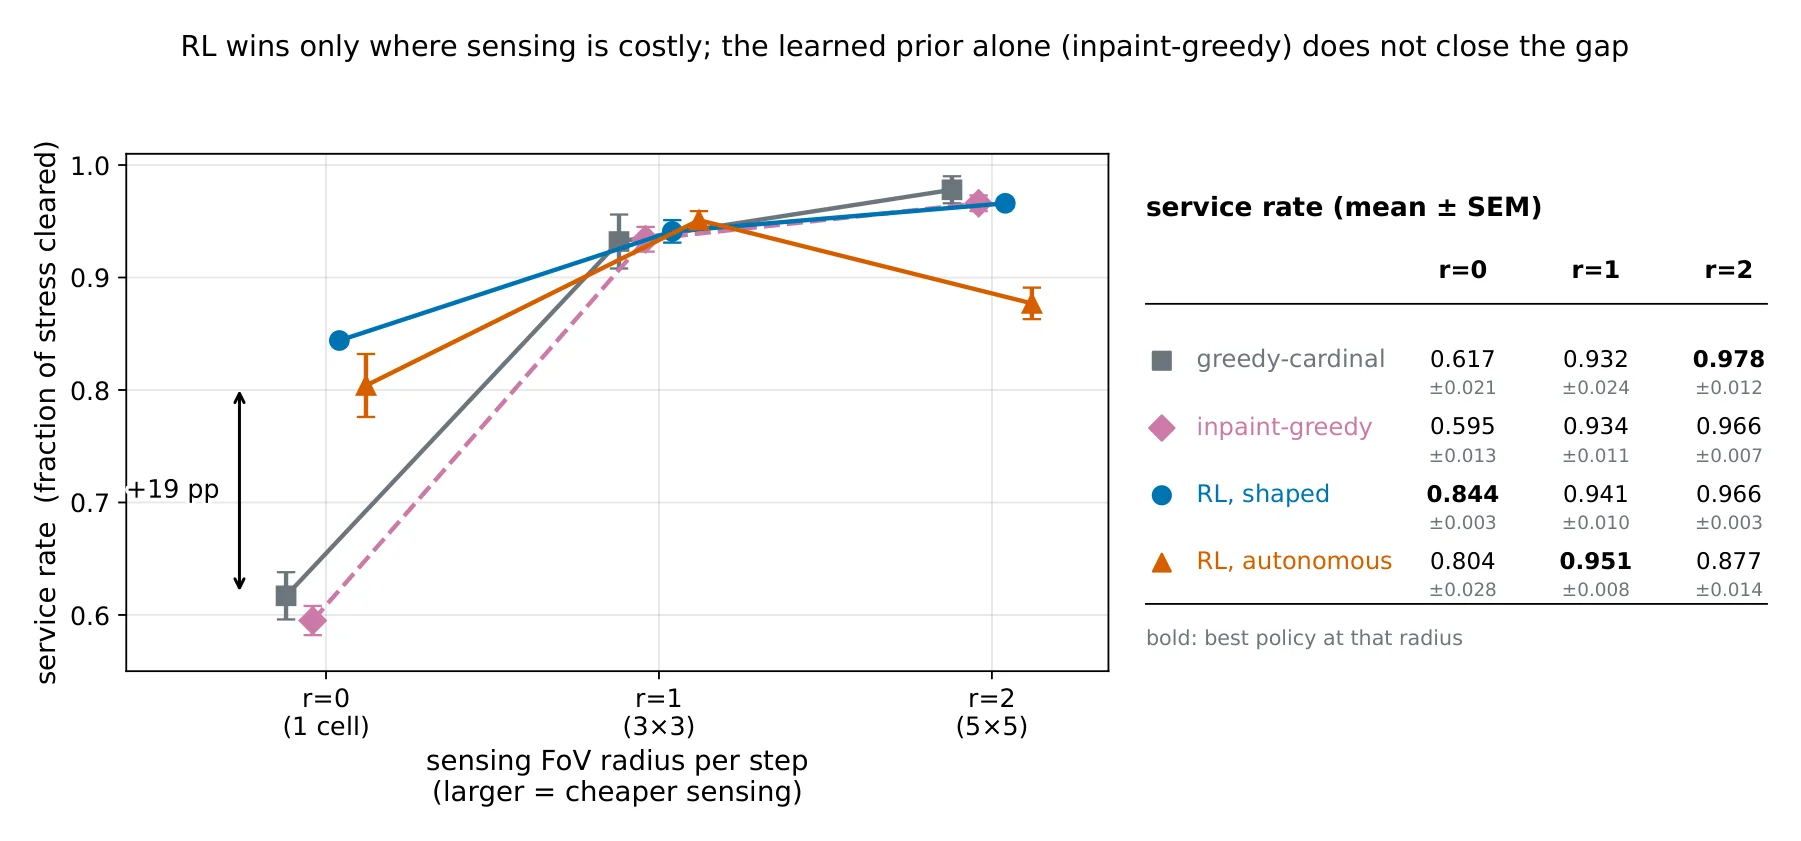
- 観測資源が不足する場合は学習方策の改善が大きく、一部の継続監視では単純な巡回も同等以上だった。
論文の図
アブストラクト(原文)
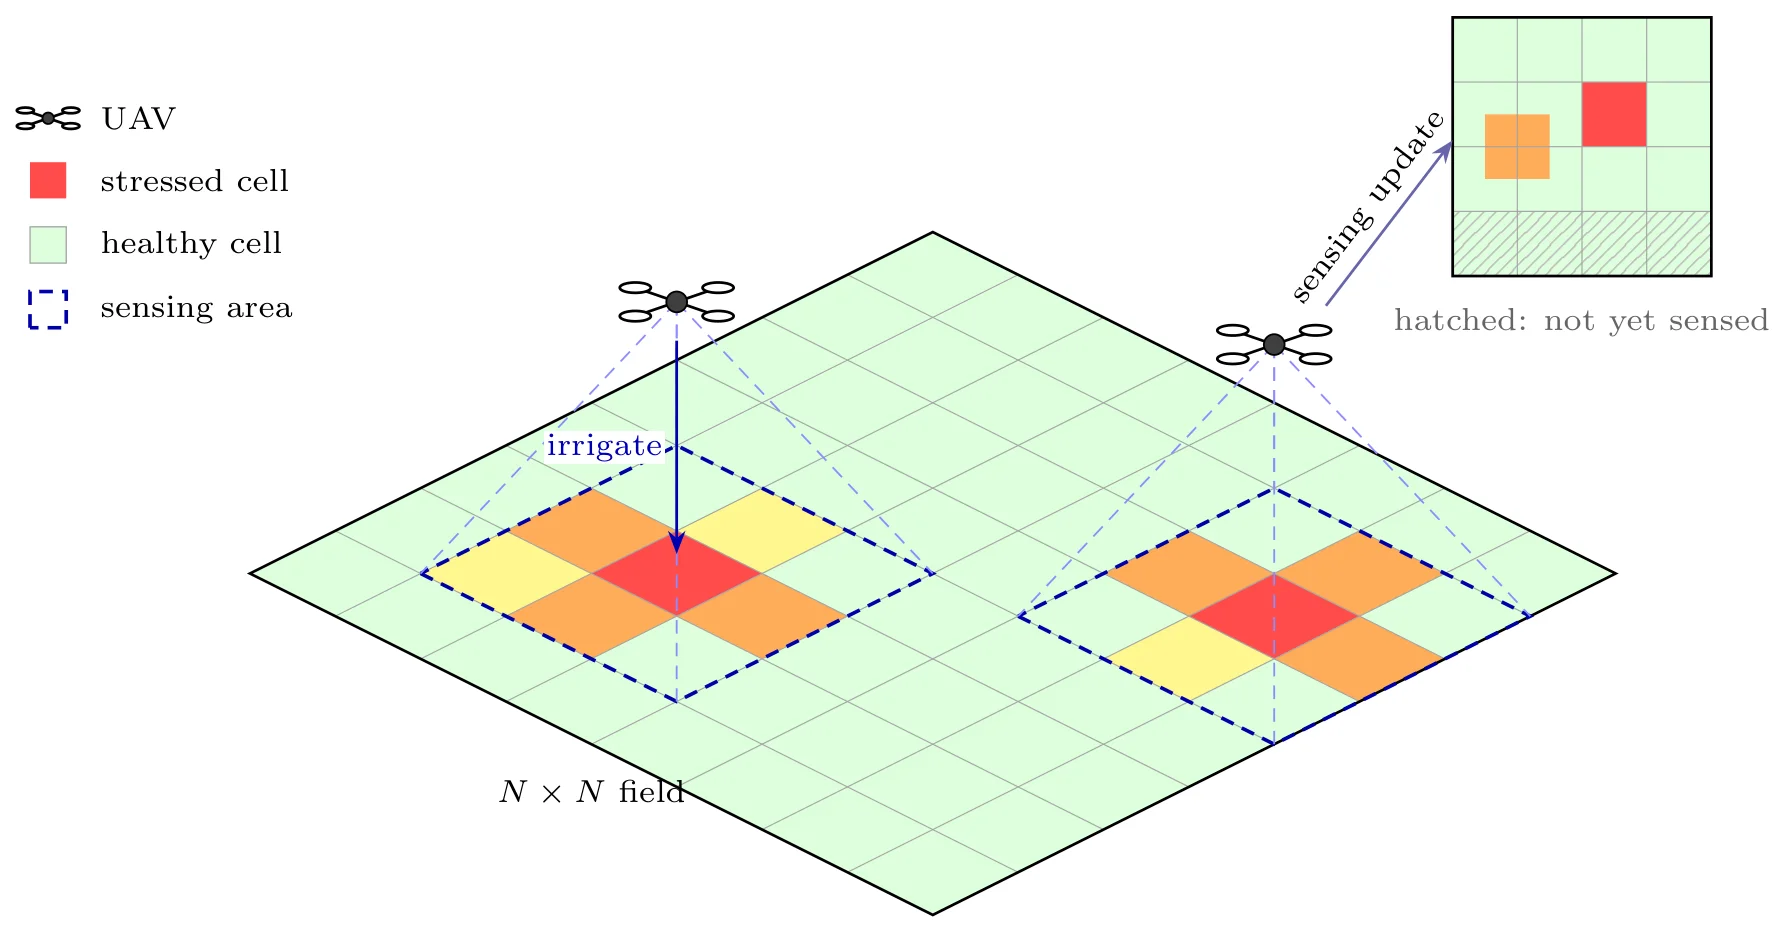
This thesis investigates the application of unmanned aerial vehicles (UAVs) as auxiliary platforms for smart agriculture, performing tasks such as precision detection, recognition, and trajectory planning. We ask when a learned policy outperforms a strong engineered heuristic in multi-agent cooperative coverage, and answer with controlled simulations. By formulating the trajectory planning problem as a Markov decision process (MDP) and employing a decentralized multi-agent reinforcement learning (MARL) framework, we analyze the impact of different sensing modalities, task scales, environmental complexity and reward models on the learning efficiency and coverage performance. Our findings indicate that value-based, feedforward primitive-action policies are effective only when sensing costs are sufficiently high and a single observation suffices to identify the local signal. Based on these insights, we propose a set of criteria grounded in sensing costs and task structure to evaluate the suitability of reinforcement learning for specific UAV coverage scenarios and to guide the selection of appropriate policy types. This provides a theoretical basis and practical guidelines for algorithm selection in similar problems.
引用方法
J. Ma, “Criteria for Reinforcement Learning Suitability in Multi-UAV Precision-Agriculture Coverage: Sensing Cost, Task Structure, and Policy Selection,” in Master Thesis, Graduate School of Information Science and Technology, The University of Tokyo, 2026.
BibTeX
@mastersthesis{Ma2026,
  title         = {Criteria for Reinforcement Learning Suitability in Multi-UAV Precision-Agriculture Coverage: Sensing Cost, Task Structure, and Policy Selection},
  author        = {Junqing Ma},
  year          = {2026},
  date          = {2026-09-30},
  urldate       = {2026-09-30},
  school        = {Master Thesis, Graduate School of Information Science and Technology, The University of Tokyo},
  abstract      = {This thesis investigates the application of unmanned aerial vehicles (UAVs) as auxiliary platforms for smart agriculture, performing tasks such as precision detection, recognition, and trajectory planning. We ask when a learned policy outperforms a strong engineered heuristic in multi-agent cooperative coverage, and answer with controlled simulations. By formulating the trajectory planning problem as a Markov decision process (MDP) and employing a decentralized multi-agent reinforcement learning (MARL) framework, we analyze the impact of different sensing modalities, task scales, environmental complexity and reward models on the learning efficiency and coverage performance. Our findings indicate that value-based, feedforward primitive-action policies are effective only when sensing costs are sufficiently high and a single observation suffices to identify the local signal. Based on these insights, we propose a set of criteria grounded in sensing costs and task structure to evaluate the suitability of reinforcement learning for specific UAV coverage scenarios and to guide the selection of appropriate policy types. This provides a theoretical basis and practical guidelines for algorithm selection in similar problems.},
  keywords      = {Thesis},
  pubstate      = {published},
  tppubtype     = {mastersthesis}
}