
HERO: Heterogeneous Evidential Robust Object-Level Collaborative Perception
19th European Conference on Computer Vision (ECCV 2026), Malmö, Sweden, 2026年9月8日
3行要約
- HEROは異なる認識モデル間で、3D物体候補と不確かさを圧縮して共有する。
- 受信側で遅延を補償し、姿勢の整合を補正したうえで、信頼度に応じて候補を融合する。
- 姿勢誤差と伝送遅延がある実験で、競争力のある検出精度を維持した。
論文の図
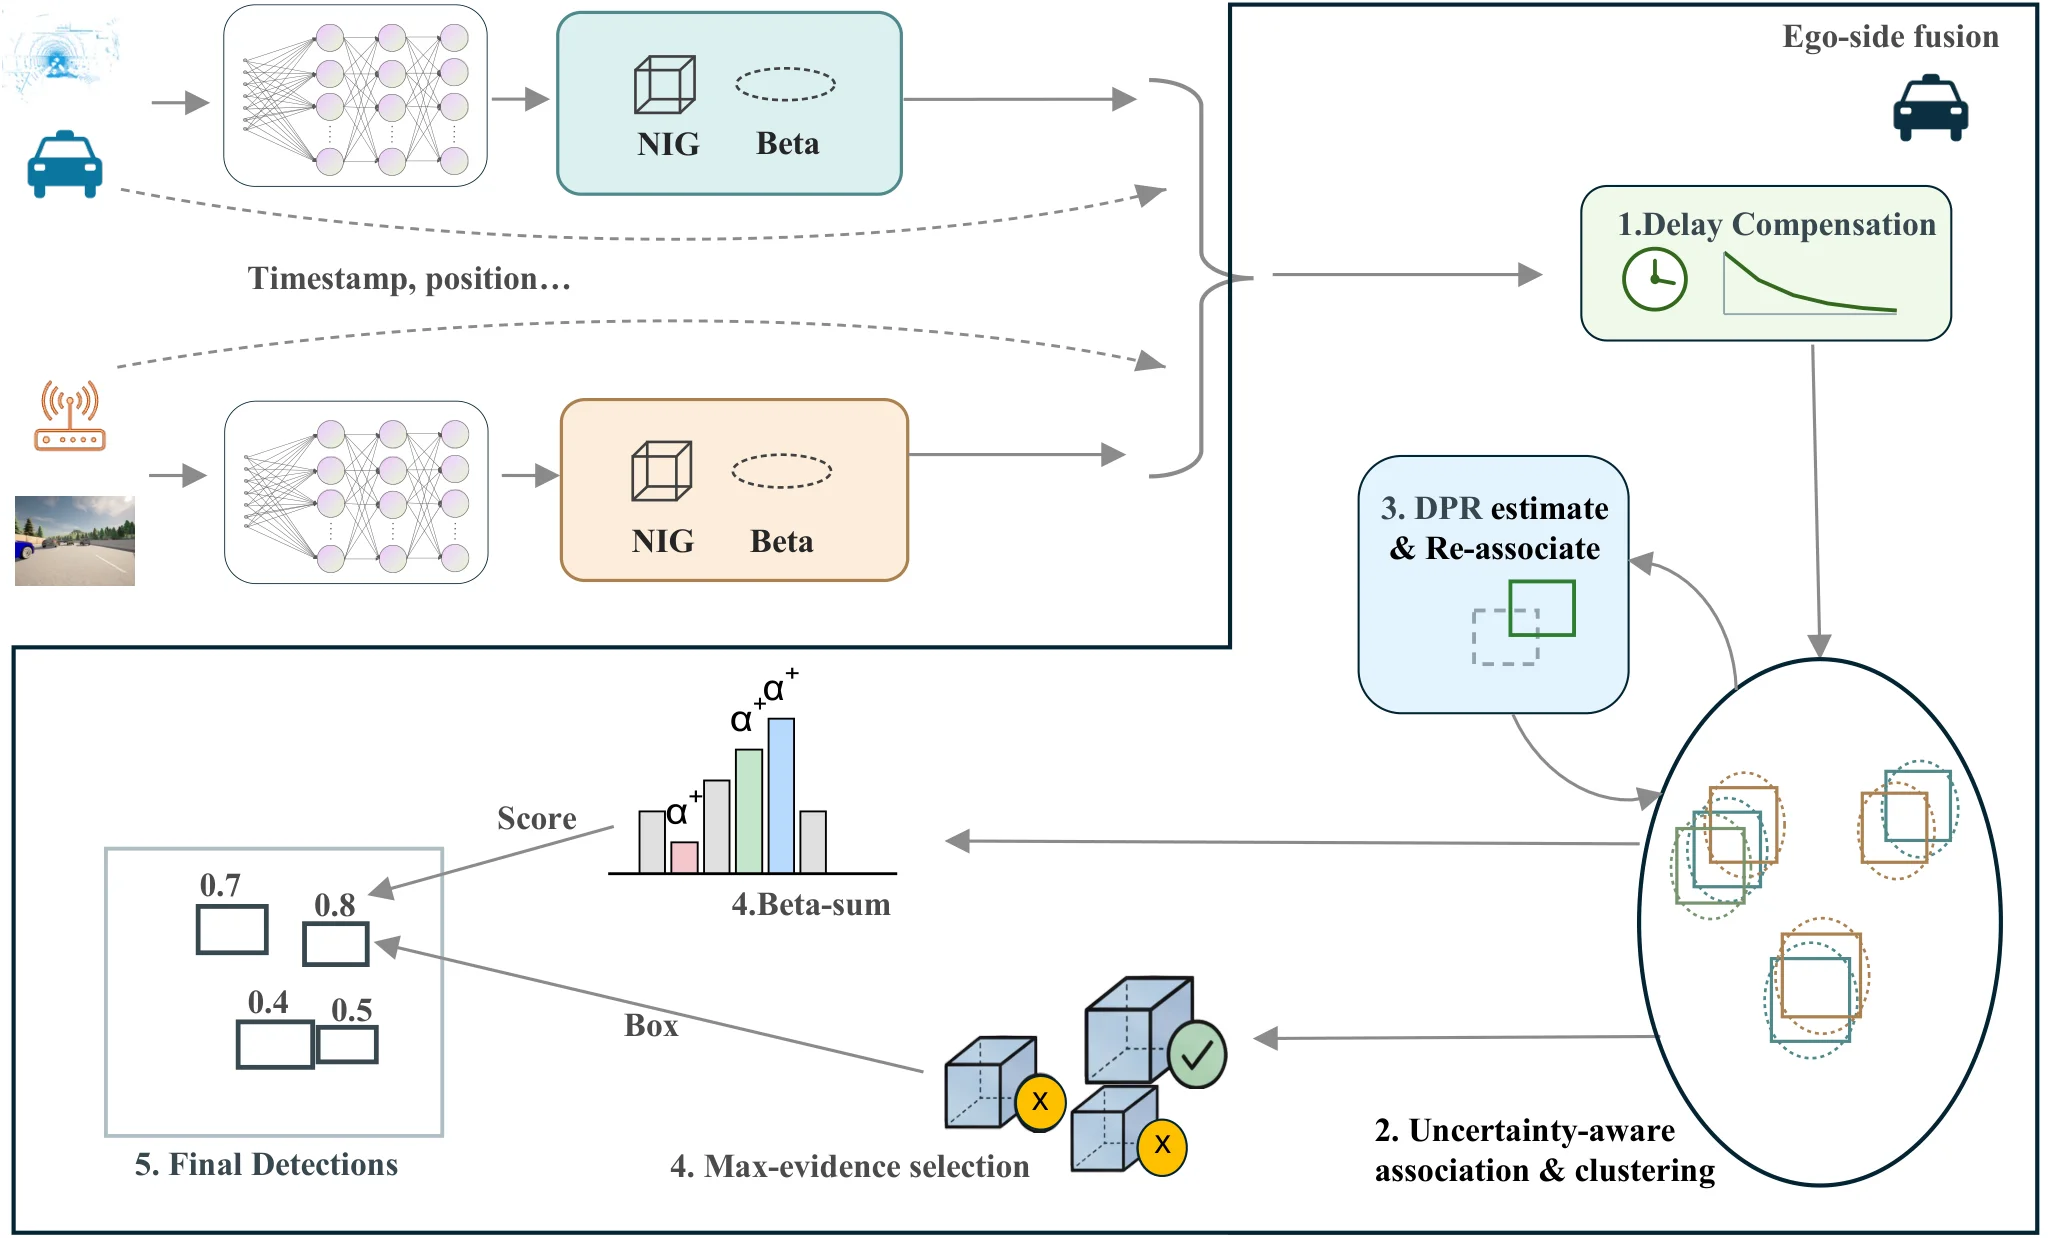
アブストラクト(原文)
Real-world collaborative perception agents typically deploy diverse sensor configurations and network architectures. While feature-level fusion methods address this heterogeneity by aligning feature spaces, they require collaborative training and large communication overhead. In contrast, object-level fusion sidesteps these constraints, as transmitted bounding boxes are directly usable across varying architectures. However, standard late fusion relies only on box coordinates and confidence scores, which provide insufficient information for robust association and leave the system vulnerable to localization noise and asynchronous delays. To address this, we propose HERO, an uncertainty-guided object-level collaborative perception method that equips proposals with evidential statistics and uses the uncertainty signals to perform robust association and fusion under pose noise and asynchrony. Experiments on OPV2V-H and DAIR-V2X show that HERO matches the SOTA feature-level fusion methods while reducing bandwidth by over 1000 times. Under localization error and latency scenarios, HERO further outperforms feature-level SOTA models.
引用方法
H. Si, E. Javanmardi, H. Wu, and M. Tsukada, “HERO: Heterogeneous Evidential Robust Object-Level Collaborative Perception,” in 19th European Conference on Computer Vision (ECCV 2026), Malmö, Sweden, 2026.
BibTeX
@inproceedings{nokey,
  title         = {HERO: Heterogeneous Evidential Robust Object-Level Collaborative Perception},
  author        = {Hao Si and Ehsan Javanmardi and Hanlin Wu and Manabu Tsukada},
  year          = {2026},
  date          = {2026-09-08},
  booktitle     = {19th European Conference on Computer Vision (ECCV 2026)},
  address       = {Malmö, Sweden},
  abstract      = {Real-world collaborative perception agents typically deploy diverse sensor configurations and network architectures. While feature-level fusion methods address this heterogeneity by aligning feature spaces, they require collaborative training and large communication overhead. In contrast, object-level fusion sidesteps these constraints, as transmitted bounding boxes are directly usable across varying architectures. However, standard late fusion relies only on box coordinates and confidence scores, which provide insufficient information for robust association and leave the system vulnerable to localization noise and asynchronous delays. To address this, we propose HERO, an uncertainty-guided object-level collaborative perception method that equips proposals with evidential statistics and uses the uncertainty signals to perform robust association and fusion under pose noise and asynchrony. Experiments on OPV2V-H and DAIR-V2X show that HERO matches the SOTA feature-level fusion methods while reducing bandwidth by over 1000 times. Under localization error and latency scenarios, HERO further outperforms feature-level SOTA models.},
  keywords      = {CRONOS, ITS},
  pubstate      = {published},
  tppubtype     = {inproceedings}
}