
CRONOS Project Landing Page
CRONOS Project
Member Introduction
-

Lei Ma
Associate Professor, The University of Tokyo
-

Hideki Nakayama
Professor, The University of Tokyo
-

Takeo Igarashi
Professor, The University of Tokyo
-

Manabu Tsukada
Associate Professor
Resources
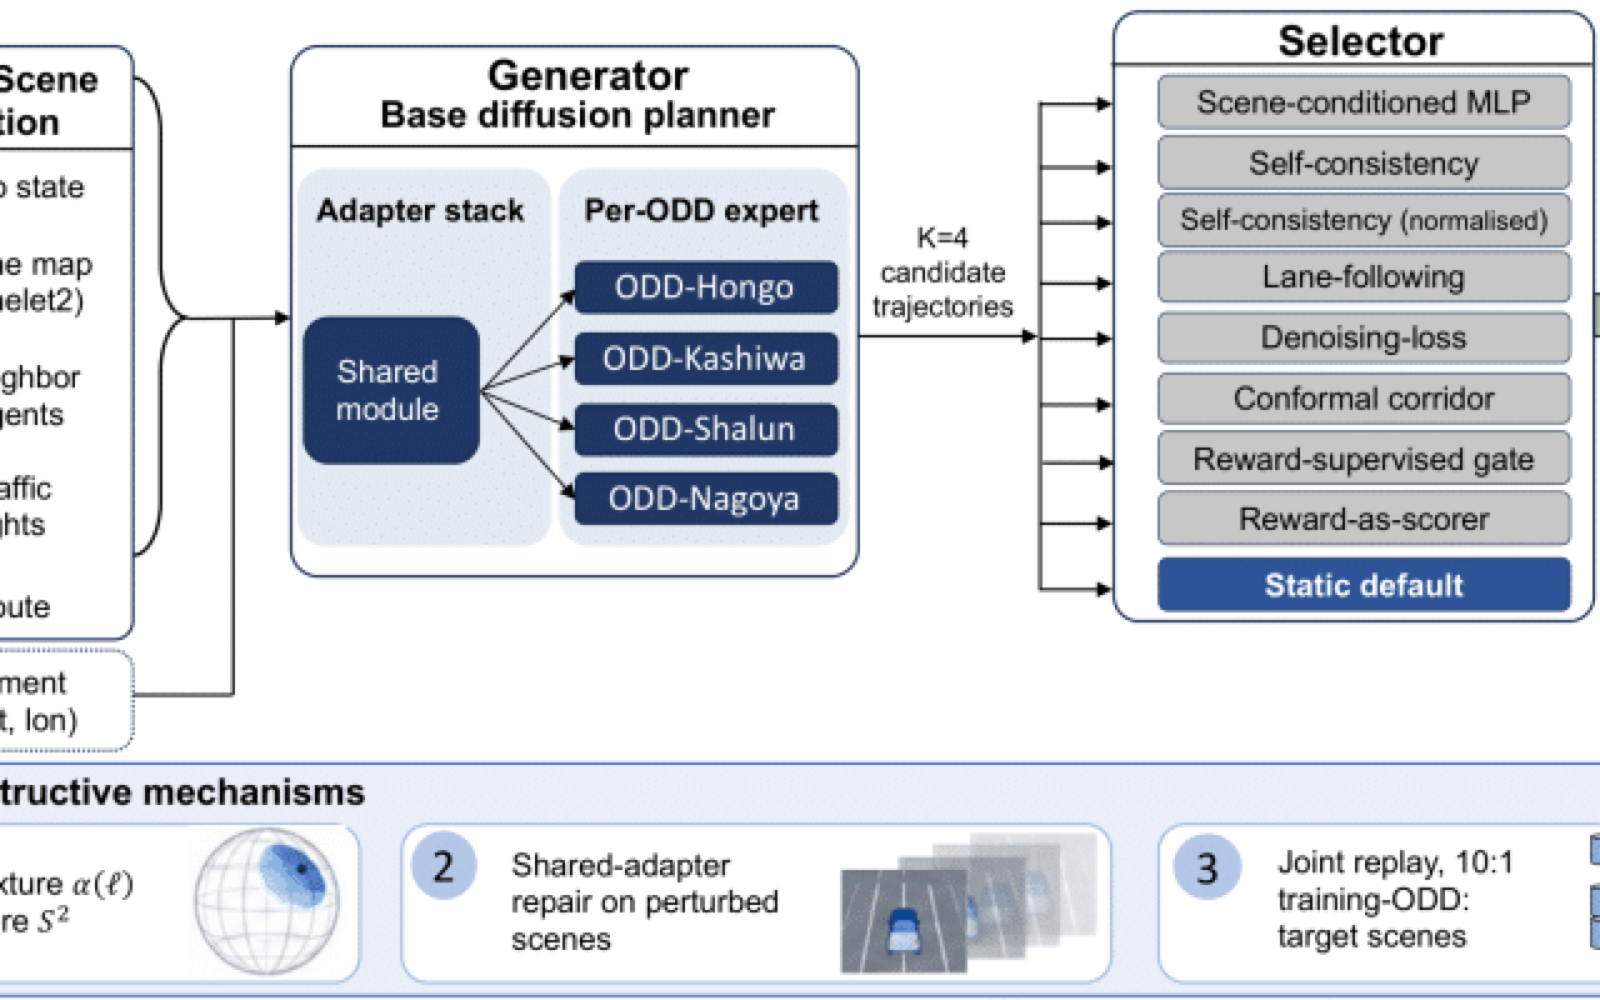
To Route or to Adapt? Multi-Expert Diffusion Planners in Unseen Regions
open source
To Route or to Adapt? Multi-Expert Diffusion Planners in Unseen Regions
open source
To Route or to Adapt? Multi-Expert Diffusion Planners in Unseen Regions
open source
To Route or to Adapt? Multi-Expert Diffusion Planners in Unseen Regions
2026-10-19

RealSim-CP Dataset
open data
RealSim-CP Dataset
open data
RealSim-CP Dataset
open data
RealSim-CP Dataset
2026-06-15
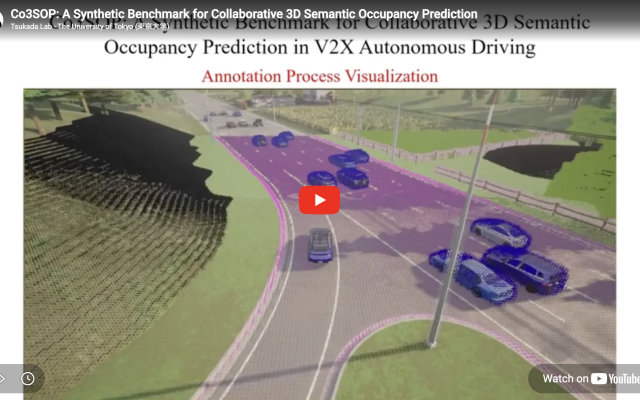
Collaborative 3D Semantic Occupancy Prediction for V2X-Enabled Autonomous Driving
autonomous driving machine learning
Collaborative 3D Semantic Occupancy Prediction for V2X-Enabled Autonomous Driving
autonomous driving machine learning
Collaborative 3D Semantic Occupancy Prediction for V2X-Enabled Autonomous Driving
autonomous driving machine learning
Collaborative 3D Semantic Occupancy Prediction for V2X-Enabled Autonomous Driving
2026-05-16
Trajectory Planning for 6G Next-Generation UAVs/AMRs
machine learning uav
Trajectory Planning for 6G Next-Generation UAVs/AMRs
machine learning uav
Trajectory Planning for 6G Next-Generation UAVs/AMRs
machine learning uav
Trajectory Planning for 6G Next-Generation UAVs/AMRs
2026-05-16
autonomous driving v2x
autonomous driving v2x
autonomous driving v2x
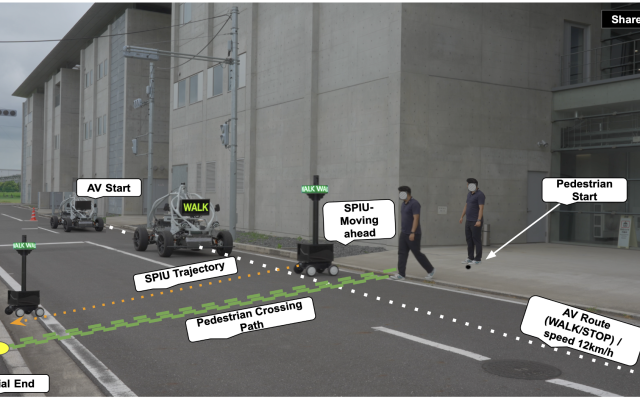
Smart Pole Interaction Unit (SPIU): Infrastructure-Side Communication for Pedestrian-AV Interaction in Shared Spaces
2026-04-06
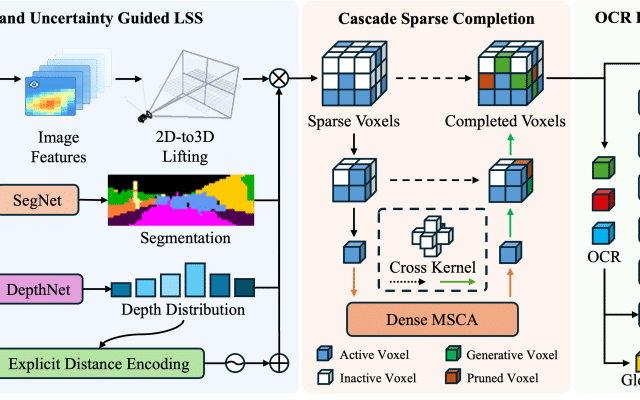
SUGOcc: An Explicit Semantics and Uncertainty Guided Sparse Learning Framework for Real-Time 3D Occupancy Prediction
open source
SUGOcc: An Explicit Semantics and Uncertainty Guided Sparse Learning Framework for Real-Time 3D Occupancy Prediction
open source
open source
SUGOcc: An Explicit Semantics and Uncertainty Guided Sparse Learning Framework for Real-Time 3D Occupancy Prediction
2026-02-27
See more software and resources
Publications
Yun Li, Ehsan Javanmardi, Simon Thompson, Jiachen Gong, Qunli Zhang, Zifan Zeng, Shiming Liu, Peng Wang, Yidu Zhang, Manabu Tsukada, “To Route or to Adapt? Multi-Expert Diffusion Planners in Unseen Regions”, In: Conference on Robot Learning (CoRL 2026), Austin, Texas, USA, 2026.Proceedings Article | Abstract | BibTeX | Links:
@inproceedings{Li2026e,
title = {To Route or to Adapt? Multi-Expert Diffusion Planners in Unseen Regions},
author = {Yun Li and Ehsan Javanmardi and Simon Thompson and Jiachen Gong and Qunli Zhang and Zifan Zeng and Shiming Liu and Peng Wang and Yidu Zhang and Manabu Tsukada},
url = {https://arxiv.org/abs/2610.31095
https://github.com/tlab-wide/RouteOrAdapt},
year = {2026},
date = {2026-11-09},
urldate = {2026-11-09},
booktitle = {Conference on Robot Learning (CoRL 2026)},
address = {Austin, Texas, USA},
abstract = {Diffusion trajectory planners with domain-specific experts face a practical question in unseen regions: can they rely on selecting among existing experts, or must the planner itself adapt? We study this question using a planner with a shared adapter and per-domain expert adapters. Across three real-world held-out maps, none of eight test-time routing schemes improves the fleet-mean lateral offset over the static default, which uses the same expert for every scene. Even an oracle that selects the best expert for each scene reduces the mean offset by only 0.9 m. In contrast, reward-based fine-tuning on just 20 target-region scenes yields substantially larger gains. On matched evaluation slices, joint replay achieves a fleet-mean offset of 6.9 m, compared with 12.4 m for the static default. Comparisons under the same target-region training budget show that target-region training drives the improvement, while replaying training scenes limits forgetting on the original ODDs. On nuPlan, fine-tuning across training cities also improves open-loop offsets, although closed-loop performance deteriorates. Further diagnostics reveal that two test-time adaptation baselines achieve low offsets by producing degenerate trajectories. These results show the limited headroom for selecting among existing experts and the greater open-loop gains available from adapting the planner.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Close
Diffusion trajectory planners with domain-specific experts face a practical question in unseen regions: can they rely on selecting among existing experts, or must the planner itself adapt? We study this question using a planner with a shared adapter and per-domain expert adapters. Across three real-world held-out maps, none of eight test-time routing schemes improves the fleet-mean lateral offset over the static default, which uses the same expert for every scene. Even an oracle that selects the best expert for each scene reduces the mean offset by only 0.9 m. In contrast, reward-based fine-tuning on just 20 target-region scenes yields substantially larger gains. On matched evaluation slices, joint replay achieves a fleet-mean offset of 6.9 m, compared with 12.4 m for the static default. Comparisons under the same target-region training budget show that target-region training drives the improvement, while replaying training scenes limits forgetting on the original ODDs. On nuPlan, fine-tuning across training cities also improves open-loop offsets, although closed-loop performance deteriorates. Further diagnostics reveal that two test-time adaptation baselines achieve low offsets by producing degenerate trajectories. These results show the limited headroom for selecting among existing experts and the greater open-loop gains available from adapting the planner.
Close
Sakura Akahoshi, Mizuki Taniguchi, Manabu Tsukada, Makoto Itoh, “Pedestrian Information Needs for eHMI Design Across Visibility Conditions: A Gap Analysis of ISO/PAS 23735”, In: Proceedings of the Human Factors and Ergonomics Society Annual Meeting (ASPIRE 2026), Reno, NV, USA, 2026.Proceedings Article | Abstract | BibTeX
@inproceedings{Akahoshi2026,
title = {Pedestrian Information Needs for eHMI Design Across Visibility Conditions: A Gap Analysis of ISO/PAS 23735},
author = {Sakura Akahoshi and Mizuki Taniguchi and Manabu Tsukada and Makoto Itoh},
year = {2026},
date = {2026-10-19},
urldate = {2026-10-19},
booktitle = {Proceedings of the Human Factors and Ergonomics Society Annual Meeting (ASPIRE 2026)},
address = {Reno, NV, USA},
abstract = {As automated vehicles remove the interpersonal cues pedestrians rely on when crossing, external human-machine interfaces (eHMIs) have been proposed as an alternative means of communication. ISO/PAS 23735:2025 defines seven information types for eHMI design, yet whether these categories fully cover pedestrian needs across varying visibility conditions remains unclear. In a within-subjects study, 30 pedestrians described their information needs across four crossing scenarios spanning full to zero vehicle visibility. Under good visibility, intent dominated and ISO/PAS 23735 coverage reached 96.6-100.0%. Under complete occlusion, coverage dropped to 26.7%; two absent categories account for the gap: presence (vehicle existence and approach confirmation), required by 93.3% of participants, and spatial information (real-time position, direction, distance, and time-to-contact), required by 30.0%. Pedestrian information needs shift qualitatively with visibility, and low-visibility conditions introduce requirements beyond the framework’s intended scope. A Visibility-Adaptive Information Framework is proposed to address this shift.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Close
As automated vehicles remove the interpersonal cues pedestrians rely on when crossing, external human-machine interfaces (eHMIs) have been proposed as an alternative means of communication. ISO/PAS 23735:2025 defines seven information types for eHMI design, yet whether these categories fully cover pedestrian needs across varying visibility conditions remains unclear. In a within-subjects study, 30 pedestrians described their information needs across four crossing scenarios spanning full to zero vehicle visibility. Under good visibility, intent dominated and ISO/PAS 23735 coverage reached 96.6-100.0%. Under complete occlusion, coverage dropped to 26.7%; two absent categories account for the gap: presence (vehicle existence and approach confirmation), required by 93.3% of participants, and spatial information (real-time position, direction, distance, and time-to-contact), required by 30.0%. Pedestrian information needs shift qualitatively with visibility, and low-visibility conditions introduce requirements beyond the framework’s intended scope. A Visibility-Adaptive Information Framework is proposed to address this shift.
Close
Hao Si, Ehsan Javanmardi, Hanlin Wu, Manabu Tsukada , “HERO: Heterogeneous Evidential Robust Object-Level Collaborative Perception”, In: The 19th European Conference on Computer Vision (ECCV 2026), Malmö, Sweden, 2026.Proceedings Article | Abstract | BibTeX
@inproceedings{nokey,
title = {HERO: Heterogeneous Evidential Robust Object-Level Collaborative Perception},
author = {Hao Si and Ehsan Javanmardi and Hanlin Wu and Manabu Tsukada },
year = {2026},
date = {2026-09-08},
booktitle = {The 19th European Conference on Computer Vision (ECCV 2026)},
address = {Malmö, Sweden},
abstract = {Real-world collaborative perception agents typically deploy diverse sensor configurations and network architectures. While feature-level fusion methods address this heterogeneity by aligning feature spaces, they require collaborative training and large communication overhead. In contrast, object-level fusion sidesteps these constraints, as transmitted bounding boxes are directly usable across varying architectures. However, standard late fusion relies only on box coordinates and confidence scores, which provide insufficient information for robust association and leave the system vulnerable to localization noise and asynchronous delays. To address this, we propose HERO, an uncertainty-guided object-level collaborative perception method that equips proposals with evidential statistics and uses the uncertainty signals to perform robust association and fusion under pose noise and asynchrony. Experiments on OPV2V-H and DAIR-V2X show that HERO matches the SOTA feature-level fusion methods while reducing bandwidth by over 1000 times. Under localization error and latency scenarios, HERO further outperforms feature-level SOTA models.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Close
Real-world collaborative perception agents typically deploy diverse sensor configurations and network architectures. While feature-level fusion methods address this heterogeneity by aligning feature spaces, they require collaborative training and large communication overhead. In contrast, object-level fusion sidesteps these constraints, as transmitted bounding boxes are directly usable across varying architectures. However, standard late fusion relies only on box coordinates and confidence scores, which provide insufficient information for robust association and leave the system vulnerable to localization noise and asynchronous delays. To address this, we propose HERO, an uncertainty-guided object-level collaborative perception method that equips proposals with evidential statistics and uses the uncertainty signals to perform robust association and fusion under pose noise and asynchrony. Experiments on OPV2V-H and DAIR-V2X show that HERO matches the SOTA feature-level fusion methods while reducing bandwidth by over 1000 times. Under localization error and latency scenarios, HERO further outperforms feature-level SOTA models.
Close
Yuze Jiang, Ehsan Javanmardi, Bo Qian, Manabu Tsukada, Hiroshi Esaki, “CacheComm: A Motion-Aware Cache System for Cooperative Perception”, In: 2026 IEEE 104th Vehicular Technology Conference (VTC2026-Fall), Boston, MA, USA, 2026.Proceedings Article | Abstract | BibTeX
@inproceedings{Jiang2026b,
title = {CacheComm: A Motion-Aware Cache System for Cooperative Perception},
author = {Yuze Jiang and Ehsan Javanmardi and Bo Qian and Manabu Tsukada and Hiroshi Esaki},
year = {2026},
date = {2026-09-06},
booktitle = {2026 IEEE 104th Vehicular Technology Conference (VTC2026-Fall)},
address = {Boston, MA, USA},
abstract = {Cooperative perception enables connected and automated vehicles (CAVs) to overcome the inherent limitations of single-agent sensing by sharing perceptual information through vehicular communications. However, existing intermediate-fusion approaches treat each transmission cycle independently, re-transmitting features for the entire scene regardless of how much has actually changed, resulting in significant bandwidth waste. We propose CacheComm, a motion-aware caching framework that exploits temporal redundancy in cooperative perception by utilizing an RSU as an intermediate feature cache. The RSU maintains an up-to-date feature map of its coverage area and uses lightweight motion detection to identify scene changes. It selectively updates the cached feature map and serve the cache to CAVs based on the motion map to save communication resources. Experiments show that our system saves 10% V2X communication load under sparse CAV and limited RSU range, and up to 77% with full RSU coverage. Our method can be easily expanded to cover more area to achieve more reduction on communication cost. Saved bandwidth can be used to transmit more critical information or further increase the perception range for a CAV.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Close
Cooperative perception enables connected and automated vehicles (CAVs) to overcome the inherent limitations of single-agent sensing by sharing perceptual information through vehicular communications. However, existing intermediate-fusion approaches treat each transmission cycle independently, re-transmitting features for the entire scene regardless of how much has actually changed, resulting in significant bandwidth waste. We propose CacheComm, a motion-aware caching framework that exploits temporal redundancy in cooperative perception by utilizing an RSU as an intermediate feature cache. The RSU maintains an up-to-date feature map of its coverage area and uses lightweight motion detection to identify scene changes. It selectively updates the cached feature map and serve the cache to CAVs based on the motion map to save communication resources. Experiments show that our system saves 10% V2X communication load under sparse CAV and limited RSU range, and up to 77% with full RSU coverage. Our method can be easily expanded to cover more area to achieve more reduction on communication cost. Saved bandwidth can be used to transmit more critical information or further increase the perception range for a CAV.
Close
Ye Tao, Manabu Tsukada, Hiroshi Esaki, “TacitCollab: A Plug-and-Play V2X Safety Filter via Free-Form LLM Dialogue”, In: 2026 IEEE 103rd Vehicular Technology Conference (VTC2026-Spring), Nice, France, 2026.Proceedings Article | Abstract | BibTeX
@inproceedings{Tao2026,
title = {TacitCollab: A Plug-and-Play V2X Safety Filter via Free-Form LLM Dialogue},
author = {Ye Tao and Manabu Tsukada and Hiroshi Esaki},
year = {2026},
date = {2026-06-09},
urldate = {2026-06-09},
booktitle = {2026 IEEE 103rd Vehicular Technology Conference (VTC2026-Spring)},
address = {Nice, France},
abstract = {Autonomous vehicles increasingly rely on Vehicle-to-Everything (V2X) communication to coordinate in complex traffic scenarios. However, the existing approaches typically exchange predefined message formats such as waypoints or discrete actions, limiting their ability to handle exotic situations
that require nuanced negotiation. We propose TacitCollab, a V2X dialogue system that enables vehicles to coordinate collision avoidance through free-form natural language communication. TacitCollab leverages vision-language models to interpret traffic situations and engage in human-like dialogue, allowing vehicles
to share observations, negotiate priorities, and reach mutual agreements. The system is designed as a plug-and-play module that can be inserted into existing autonomous driving pipelines, accepting intentions in arbitrary formats and outputting updated intentions in the same format. We evaluate TacitCollab on 238 collision scenarios from the DeepAccident dataset. Results show a Collision Avoidance Ratio of 97.4%, with 84.2% of scenarios achieving coordinated outcomes where vehicles successfully
negotiate right-of-way. The average bandwidth of 1.17 KB per scenario demonstrates that text-based dialogue is practical for bandwidth-constrained V2X networks.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Close
Autonomous vehicles increasingly rely on Vehicle-to-Everything (V2X) communication to coordinate in complex traffic scenarios. However, the existing approaches typically exchange predefined message formats such as waypoints or discrete actions, limiting their ability to handle exotic situations
that require nuanced negotiation. We propose TacitCollab, a V2X dialogue system that enables vehicles to coordinate collision avoidance through free-form natural language communication. TacitCollab leverages vision-language models to interpret traffic situations and engage in human-like dialogue, allowing vehicles
to share observations, negotiate priorities, and reach mutual agreements. The system is designed as a plug-and-play module that can be inserted into existing autonomous driving pipelines, accepting intentions in arbitrary formats and outputting updated intentions in the same format. We evaluate TacitCollab on 238 collision scenarios from the DeepAccident dataset. Results show a Collision Avoidance Ratio of 97.4%, with 84.2% of scenarios achieving coordinated outcomes where vehicles successfully
negotiate right-of-way. The average bandwidth of 1.17 KB per scenario demonstrates that text-based dialogue is practical for bandwidth-constrained V2X networks.
Close
Donghui Li, Ehsan Javanmardi, Manabu Tsukada, “Aligning What Matters: Object-Centric and Structure-Aware Feature Alignment for Heterogeneous Collaborative Perception”, In: 2026 IEEE 103rd Vehicular Technology Conference (VTC2026-Spring), Nice, France, 2026.Proceedings Article | Abstract | BibTeX
@inproceedings{Li2026b,
title = {Aligning What Matters: Object-Centric and Structure-Aware Feature Alignment for Heterogeneous Collaborative Perception},
author = {Donghui Li and Ehsan Javanmardi and Manabu Tsukada},
year = {2026},
date = {2026-06-09},
booktitle = {2026 IEEE 103rd Vehicular Technology Conference (VTC2026-Spring)},
address = {Nice, France},
abstract = {Collaborative perception enhances autonomous driving by enabling vehicles to jointly reason about the environment. Feature-level sharing is particularly attractive, as it preserves rich spatial information and allows uncertain regions to be jointly refined before object inference. However, in realistic deployments, vehicles often rely on heterogeneous perception backbones and preprocessing pipelines, resulting in substantial domain gaps that make feature fusion unreliable. Recent protocol-domain adapter frameworks mitigate this issue by mapping heterogeneous features into a shared latent space, but their alignment objectives are typically defined over the entire Bird’s Eye View (BEV) grid. Since foreground objects occupy only a small fraction of BEV space, such global reconstruction objectives are dominated by background regions and provide weak supervision for aligning detection-critical features. Moreover, purely global alignment does not explicitly preserve fine-grained spatial structures that are essential for accurate 3D object detection.
In this work, we revisit protocol-domain alignment from the perspective of detection relevance and structural consistency. We propose an object-centric and structure-aware adapter for heterogeneous collaborative perception. Specifically, we introduce BEV foreground masks derived from 3D bounding boxes to emphasize object regions during alignment, and incorporate a Structural Similarity Index Measure (SSIM)–based objective to enforce fine-grained structural consistency across heterogeneous feature domains. Importantly, the proposed method preserves the plug-and-play property of protocol-domain collaboration and requires no modification of the original perception backbones or fusion modules.
Extensive experiments under diverse heterogeneous configurations demonstrate consistent improvements over protocol-domain adapter baselines, achieving up to +0.19 AP@0.7 under challenging modality settings.
},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Close
Collaborative perception enhances autonomous driving by enabling vehicles to jointly reason about the environment. Feature-level sharing is particularly attractive, as it preserves rich spatial information and allows uncertain regions to be jointly refined before object inference. However, in realistic deployments, vehicles often rely on heterogeneous perception backbones and preprocessing pipelines, resulting in substantial domain gaps that make feature fusion unreliable. Recent protocol-domain adapter frameworks mitigate this issue by mapping heterogeneous features into a shared latent space, but their alignment objectives are typically defined over the entire Bird’s Eye View (BEV) grid. Since foreground objects occupy only a small fraction of BEV space, such global reconstruction objectives are dominated by background regions and provide weak supervision for aligning detection-critical features. Moreover, purely global alignment does not explicitly preserve fine-grained spatial structures that are essential for accurate 3D object detection.
In this work, we revisit protocol-domain alignment from the perspective of detection relevance and structural consistency. We propose an object-centric and structure-aware adapter for heterogeneous collaborative perception. Specifically, we introduce BEV foreground masks derived from 3D bounding boxes to emphasize object regions during alignment, and incorporate a Structural Similarity Index Measure (SSIM)–based objective to enforce fine-grained structural consistency across heterogeneous feature domains. Importantly, the proposed method preserves the plug-and-play property of protocol-domain collaboration and requires no modification of the original perception backbones or fusion modules.
Extensive experiments under diverse heterogeneous configurations demonstrate consistent improvements over protocol-domain adapter baselines, achieving up to +0.19 AP@0.7 under challenging modality settings.
Close
Symposium
Time and Place
Monday, May 12 ⋅ 14:00 – 17:00I-REF Building 6F Hilloby
Program
14:00-14:30 CRONOS Project and activity sharing (Tsukada)
14:30-15:20 Research introduction by Prof. Igarashi, Prof. Nakayama, and Prof. Ma
15:20-15:30 (Break)
15:30-15:45 Research introduction (Progressive Heterogeneous Collaborative Perception)
15:45-16:15 Evaluation platform (CVPR Challenge overview and competition)
16:15-17:00 Discussion + poster session


Contact & Registration
- Email: tsukada-cronos-group@g.ecc.u-tokyo.ac.jp
- Address: 4F, I-REF building, Graduate School of Information Science and Technology, The University of Tokyo, 1-1-1, Yayoi, Bunkyo-ku, Tokyo, 113-8657 Japan
- Principal Investigator: Manabu Tsukada (Assoc. Prof., Graduate School of Information Science and Technology, The University of Tokyo)
- Co-PI: Takeo Igarashi (The University of Tokyo) · Hideki Nakayama (The University of Tokyo) · Lei Ma (The University of Tokyo)